Large models with 2 billion or more parameters (such as Gemma 4 E4B) tend to be reliable in tool calling in agentic systems. But as one tries smaller and smaller models, reliability drops. Sub-1B mode...
The AI bubble refers to the concept that the excitement about AI has led to excess investment. Many areas are contending with new data centers being built. The idea is that huge models, with trillions...
I have had good results with small language models (such as 1.2B parameters) for interacting with my MCP server. I decided to try to see how small I could go—if 1.2B worked, would 350M work, would 230...
Yesterday I was trying to track memory usage of some programs I was running, and was using top in Ubuntu. I can never remember how to use commands with top; in any case I found the "help" section. I d...
Now that I have an agentic AI system set up (I wrote my own local MCP server) I can test different models on it. However, it became clear in testing that occasionally a model will make a "bad" tool ca...
Currently it is not feasible (for most people) to run frontier, state-of-the-art models (LLMs) locally. Data centers are needed to run these large models. However, I remain convinced that local LLMs a...
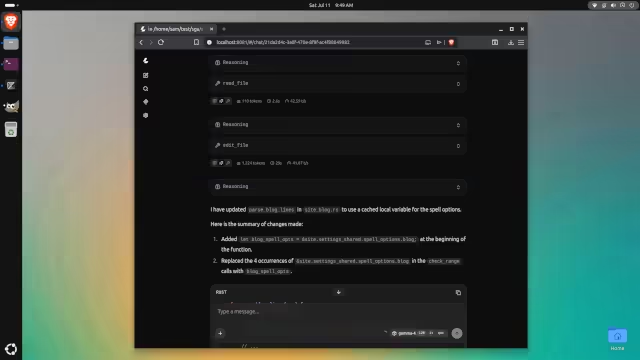
I spent an hour trying to improve a function in my Rust program. Unfortunately, after all my work, it turned out my changes made it slower, so I had to discard the new version. In dismay, I loaded a l...
When an LLM is quantized, it becomes possible to fit it onto a consumer GPU. Quantization is an important step in getting an LLM to work on many GPUs. Recently I investigated the AutoRound quantizatio...
Recently I have been using ComfyUI to generate desktop backgrounds for my Ubuntu system. I have an Nvidia GPU (RTX 3060 12 GB) so I have been able to do it entirely locally. It took me a while to figu...



 评论
 点赞
 收藏