Why we don't do prompt tracking.

TL;DR: We don't do prompt tracking because prompts are infinite variants of canonical core intent entities and we monitor those instead.
Read on though. It's worth going beyond surface claims.
Let's start with an example:
Core Entity:
- running shoes
Queries:
- buy running shoes
- running shoes online store
- where to buy running shoes
Prompts:
- I want to buy a new pair of running shoes. Where should I buy them?
- Can you recommend a good online store for running shoes?
- Where is the best place to buy running shoes?
The thing is that you can have numerous queries with the same core intent and a literal infinity of such prompts. The variations in content and are endless but the canonical form is the same.
Things we don't have, and never will, are and personalization such as user history, location, device, custom instructions and so on.
So I see people do this:
I'm a 27 year old female from Sydney looking to buy some running shoes...
My expert opinion and comment on this approach is: LOL!!!!
And clickstream?
Unethical, creepy and bundled with a looooooot of mathematical fudge, formulas and extrapolations between sparse data points. At this point you might as well just give up and make up synthetic prompts.
Even in cases where people willingly volunteer their chat history you're getting *that* demographic only. I bet you're not *it* yourself and don't know many people who are willing to surrender their most personal conversations for a small benefit or a tiny fee.
What we track instead
app.dejan.ai tracks the core entity. Each tracked entity, such as "running shoes", goes to Google, OpenAI and Anthropic models with web search on, using one fixed prompt:
Recommend brands for a user searching for the supplied query. When mentioning the brand in your response wrap each brand name like this:
[[brand]] Text goes here.Example:[[Microsoft]] A short blurb relevant to user query goes here.[[Google]] A short blurb relevant to user query goes here.
Don't enumerate.
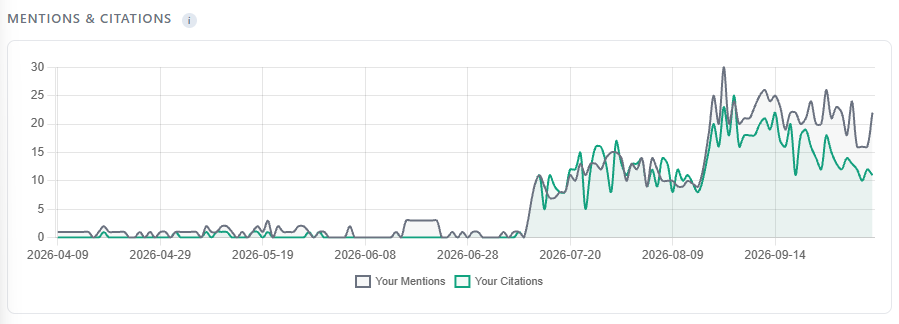
The markers let us record which brands the model names, in what order, and which pages it cites. We run the same probe for each target location on a daily, weekly or monthly cadence, and the results become visibility scores per entity, per location and per brand over time.
The wording never changes between runs, so when a brand's share moves, the cause is a change in the model or in the web results it retrieved.
We also ask the same question with web search off. That answer shows what the model knows about the market from its training data, separate from what it finds when it searches.
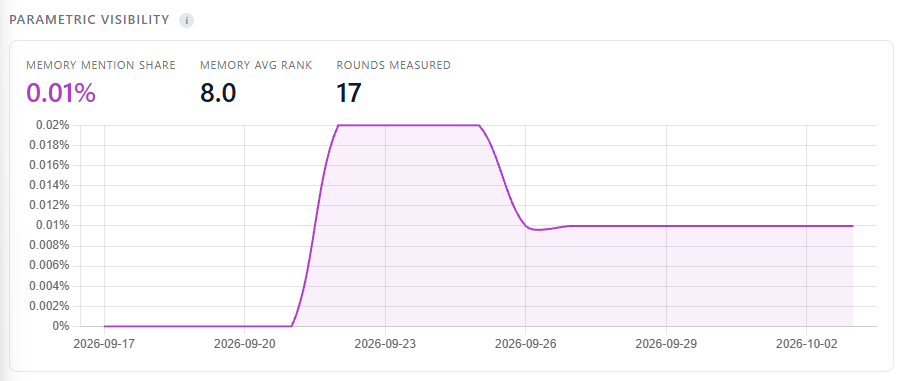
Answers vary from run to run even when the input is identical, so one answer is one sample. Our association probes repeat each entity up to 100 times, and our relevance probes take up to 100 independent samples per brand and entity pair. We report the share of answers in which a brand appears, because a single answer can change on the next run.
STOP! Read this, don't skip:
This is not what happens in the real world, the above are not the actual volumes of searches, it's also not how people search or what chat sessions look like or how models respond. There is no pretence here. This is a measurement framework that tests the impact of our SEO experiments on model behaviour in terms of selection rate and grounding presence. Neat, structured ordinal values are replacing LTR (left to right) order of recommended brands you see in naturally flowing text by the model.
Are synthetic prompts useful?
Of course they are. Prompts are super-useful for qualitative research, citation source discovery, content ideas and fanout-query capture. We use them extensively as part of our Citation Mining workflow.
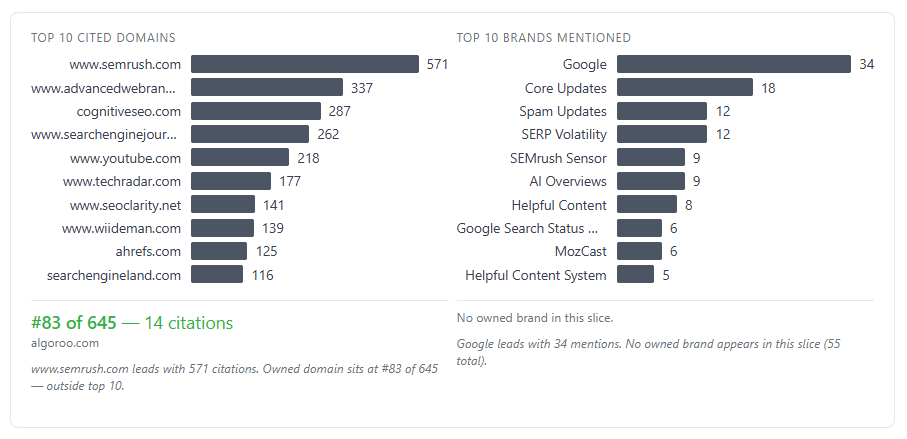
Here's an example: https://app.dejan.ai/property/43?tab=citations
What I'm saying is that freestyle synthetic prompts are the wrong tool to use for visibility tracking. You would need to work very hard to change my view on this.
Confused?
Here's a clear-headed way to think about this. There's an infinity of prompt variations with the same canonical intent. So instead of all that busywork we opt to quantize them into their most nuclear canonical form and measure that.
Why? Because the fanout queries bring the grounding context to the model, and the prompt does not.
Here's a list of 10 synthetic prompts used for citation mining:
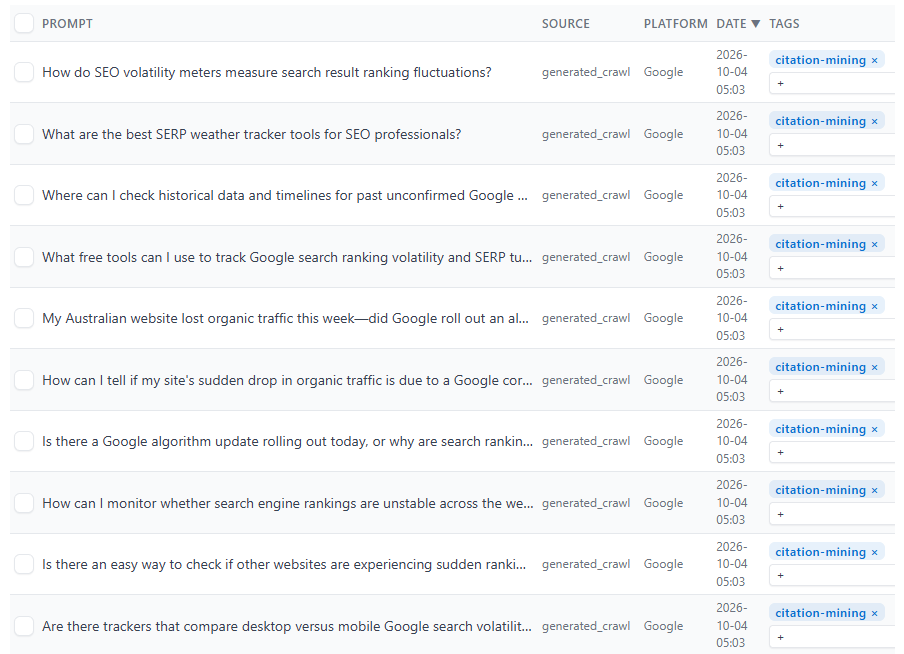
https://app.dejan.ai/property/43?tab=citations&run_id=12496&src=&view=&ent_id=&query_q=&loc=&tag_id=
And their fanouts:
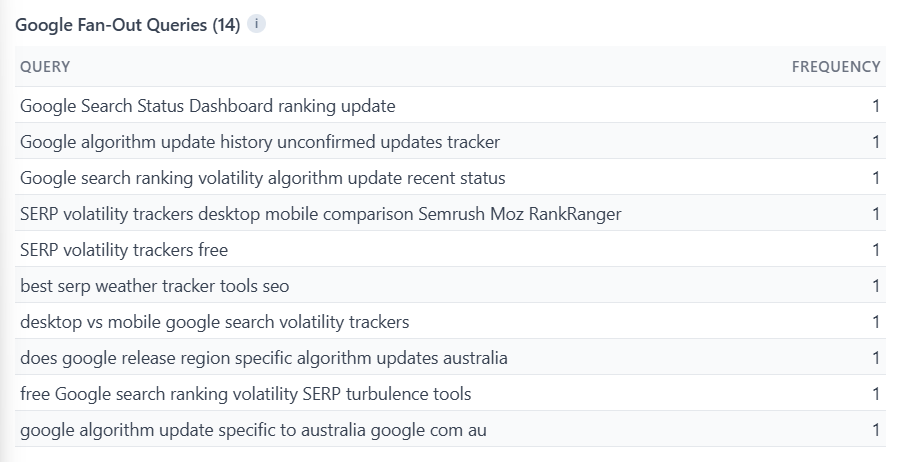
https://app.dejan.ai/property/43?tab=citations&run_id=12496&sub=fanouts&view=google
For Google, each one of the fanout queries returns a set of results, best of which are selected for inclusion as grounding candidates.
Each grounding candidate is then represented to the model as a grounding snippet generating using extractive summarization where only the most relevant parts of the page, relative to the fanout query, are extracted from the page and stitched together with ellipses "..." to form one grounding snippet.
Here's what that looks like for fanout query "SERP flux measurement tool" from one of the input prompts for Algoroo project:
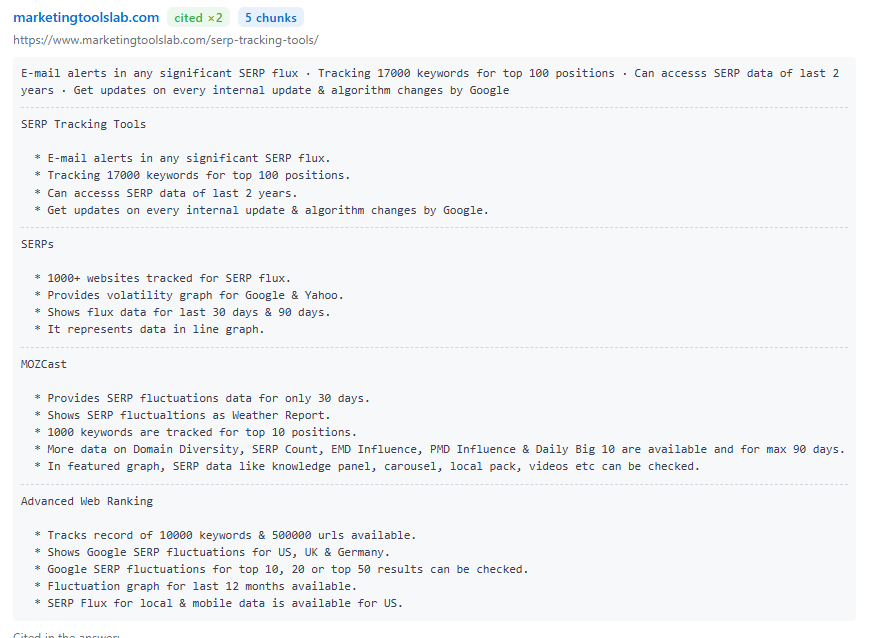
The above is from our grounding inspector tool:
https://app.dejan.ai/property/43?tab=grounding_inspector
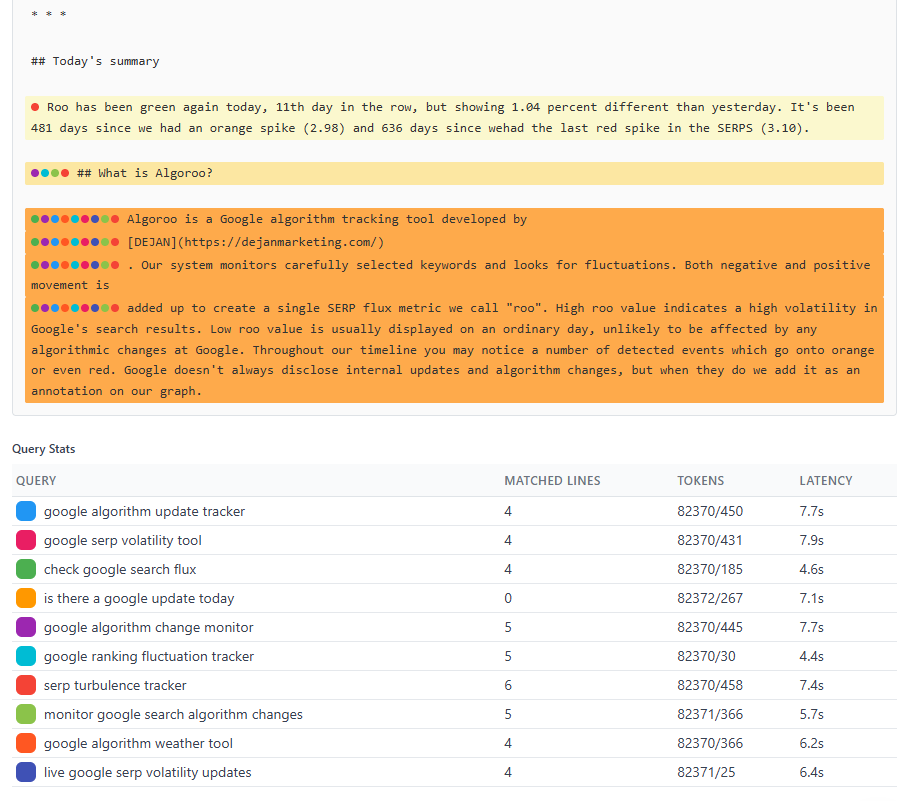
And this tool will both generate the fanouts and do the fanout heatmap on the page highlighting the most important parts of the page with respect to the fanouts for a given prompt: https://app.dejan.ai/property/43?tab=optimizer&sub=page_grounding

 点赞
 收藏
 点踩
 分享