Koopman Theory and Metaethics

tl;dr: The constructivist view of natural selection as the main source of our moral views can be expressed in a surprisingly tractable mathematical form. Measurements of the universe can be rolled forwards in time using the linear Koopman operator, and so most of its late-stage behavior is described by Koopman eigenfunctions with eigenvalue near 1. Life would then be selected for moral systems that constrain behavior within one of those slow modes. As we humans are likely influenced by this constraint, it might not be horrible to use spectral analysis as part of our moral reasoning.
tl;dr tl;dr: Local Teenager Tries To Solve Ethics With Funny-Looking K
You and Your Values
It’s remarkable that our decisions even somewhat align with any coherent moral philosophy so far put forth. Neuroscience has hardly begun to peer into the human brain, and evolutionary psychology seems far from settled enough to give strong predictions. Approval reward mediates most of our agreement with each other in communities, sure. But it doesn’t explain the "moral arc of history," or agreement between disconnected human groups. So, what gives? Where and why do we agree with each other?
"Moral Arc of History"
In everyday situations, you seem to act as if you had coherent preferences. Your behavior reasonably controls your hunger, blood CO2 concentration, bladder pressure, and so on. While there is significantly more disagreement in terms of cultural questions, at least some historic issues seem to have converged over time, such as appraisals of slavery and murder. In contrast, by default, we seem to make choices distributed ~uniformly in new situations (e.g. the red/blue button poll). As such, there seems to be some qualitative spectrum going from the most decided issues to the least decided issues based on how novel they are.
As such, it would be nice if we could somehow speed up the reasoning process that makes people converge on an answer. If it turns out that animals deserve more moral weight, for instance, I would hope it would take less time for humanity to figure that out than was required for slavery. So what exactly is improving our morality over time?
One possible starting point is evolution. Genetic/memetic selection was at least partially responsible for resolved issues (see this post), but clearly we’re not fitness maximizers, so evolution might be limited in some way.
But if natural selection was blind to some aspect of our values, it leaves the question of where they even came from. In fact, the following model describing somewhat-general agents implies that our values are not as far from natural selection as they might seem.
Intuition for Moral Constructivism
Agents, for the purpose of the argument, are just things that can copy themselves in the right environment. Agents have three things happen to them: (1) they can start to exist or (2) stop existing due to physics, and (3) they can change their stance on a value (through their brains or whatever makes decisions for them). This fully accounts for the changes in the population of a value. If agents are physically fragile and cannot modify themselves physically, then there's some unbroken line of organisms between abiogenesis and ourselves. We should be able to pinpoint where each value comes from on this line.
So, where did, for example, justice come from? We can say that practically nothing like justice was factored into some organism in our evolutionary past, such as asexually reproducing bacteria. Roughly speaking, the transition point where positive stances on justice appeared could come from two situations: (1) selection on physical substrates for an instinctual sense of justice or (2) some sort of convincing event, where agents with no instinctual "justice" used “reason” to find it and take it as a moral fact. The first case is pretty obviously connected to natural selection. Technically, genetic drift and randomness could have also played a role, but given the complexity of the brain, it should be minor. The second case does rely on this weird "reason" thing, however.
And yet, reason is not mysterious. The capacity to be reasoned into having a positive stance on justice is itself under selection. As it didn’t exist at abiogenesis, there was some point in the past where that capacity must have been selected for. That is, at some point, an element of reason increased fitness, and that element also happened to predispose organisms for valuing justice. The justice component may have been why it was adaptive, or maybe not, but this element was still locally adaptive regardless. In any case, the value of justice is connected back to selective pressures somewhere in the past.
In general, any moral value works here. So any value we currently take into consideration was a result of a series of selection events, nearly all of which increased fitness at the time they were made.
The Longer Term
Of course, it's simple to imagine this “series of selection events” going in a self-destructive way. One could imagine some purity-like trait (either memetic or genetic) that gets agents to force others to follow an increasingly strict list of rules, doling out extreme consequences for rule-breakers (think of the electric-shock country from Meditations on Moloch). This sets up a series of selection events rapidly favoring those setting rules (and following them). However, any population that gets stuck in this trap is obviously going to evolve to extinction without a way to stop it. So evolution may not be as blind as it’s often said to be; it does take the wrong turn quite frequently, but it eventually makes its way through if it can backtrack at least once.
But "selection events" can take an arbitrary amount of time. If a second population did not fall into this trap, would it not be that over the longer term of this experiment, a "selection event" has occurred favoring the second population? In fact, selection events can also encompass various smaller selection events occurring on different scales and in different environments.
In one conversation I had with someone, they brought up that moral systems purely based on evolution would, for example, recommend men to repeatedly donate to sperm banks or set up eugenics organizations. The problem with these recommendations is that they only work in the short term. The sperm bank scenario would lead to selection against societies encouraging sperm bank use. Such societies would suffer more inbreeding and more Goodharting towards qualifying for donations, and selection of other positive traits would slow. Even if a society couldn't avoid its influence, the long-term effects of this runaway selection would decrease its relative fitness compared to other populations (i.e. the hypothetical clone that never fell into the trap). As for the eugenics organizations, I would have to note that such an institution is incredibly vulnerable to exploitation (if it wasn't already set up for that). While I would theoretically be fine with a very thoughtful eugenics organization, in practice, they would be in a very unstable equilibrium (and all historical examples of eugenics show as much).
As these examples show, longer-term considerations likely make up for a lot of the hidden complexity in human values. In general, it seems bad to enter self-defeating regimes, especially those that irretrievably hoover up resources: more succinctly, it seems that cancer is bad.
Unfortunately, it's much harder to conceptualize every possible selection event at once. It involves multiple different size and time scales, requires accounting of non-obvious resources, and in general deals with a chaotic, non-linear dynamical system. Wait a second!
The Koopman Operator
The Koopman operator is a nifty function that simulates time going forward in any system. It's not defined on the system itself, but instead on "measurements" or "observables," which are functions of the underlying system that produce a scalar output. Consider a dynamical system mapping the set of system states to itself, advancing one step at a time. Then, the discrete Koopman operator associated with is defined to turn the observable into a separate observable that applies after a single timestep. The formal definition uses composition:
The Koopman operator also happens to be linear in every dynamical system. Accordingly, the Koopman operator can have eigenvectors on the vector space of observables, or more properly, eigenfunctions. As you may have noticed, a function space is infinite-dimensional, containing such wonders as and , so the solutions can be similarly complex.
Refresher on eigenvectors/eigenfunctions/modes
An eigenvector is a vector in the domain and range of a linear operator such that, for some scaling factor ,
The key idea is that the eigenvector points in the same direction even after being transformed. You can see this in the below graph from 3Blue1Brown, where the vector is simply rescaled by a factor of 2:
As such, eigenvectors are a natural way to look at the function of the operator itself.
Eigenfunctions are just a special name for eigenvectors when they are themselves functions, and “modes” are mostly synonymous. The full list of eigenfunctions is also called a "spectrum."
Concrete example of analytically finding Koopman eigenfunctions
Consider the simple discrete-time system on acting on states so that. To get a handle on this, let's evaluate on the observable . We can quite easily evaluate the Koopman operator's effect on it:
So what are the eigenfunctions of on ?
As for , we get the constant eigenfunction. This, of course, has eigenvalue 1. There's a similar family of eigenfunctions: the exponentials of , like , , , etc., as . A sneakier family of eigenfunctions also exists, however!
With a little trial and error, one can find that (like ) is an invariant of this system that never changes along any trajectory, while also remaining constant. Therefore, it, along with every possible function of it, is a 1-eigenfunction like the constant eigenfunction. The even subtler is also invariant, as we are working in a discrete system. Finally, one can arbitrarily multiply these eigenfunctions together. (I could give a more thorough treatment of continuous Koopman theory, but it boils down to parametrizing by a real timestep.)
The Koopman operator has been the hot new thing lately in dynamical systems theory. In most cases, one doesn't have an exact analytical form for a system's dynamics, but a series of algorithms called Dynamic Mode Decomposition (DMD) can be used to estimate Koopman eigenfunctions if you chuck enough data into it. For instance, it can pick out spatiotemporal modes (eigenfunctions constant relative to time but not space), helping to decompose certain complex patterns:
With algorithms capable of finding more complex eigenfunctions, one can even start to make decent predictions about otherwise rather chaotic systems (see here for an analysis of the Lorenz attractor in Figure 5.1). Otherwise, it's been one niche among a multitude of options for understanding non-linear dynamical systems (e.g. the transfer operator, compressed sensing, stochastic stability, etc.)
However, the Koopman operator is well-suited to handle the multiple time-scales on which natural selection acts. This property motivates the use of Koopman theory specifically to approximate where human morality and decision-making may have ended up, reducing the Hidden Complexity of Wishes.
Koopman All the Things
The trick is to take the Koopman operator of reality itself. Given the various observables that we humans have access to, it seems it should be possible for us to find a "long-lasting eigenfunction" with our models of reality and then "ride it," so to speak.
Unfortunately, there are many practical challenges stemming from the math itself preventing us from doing that. The first one is that if a moral system only tracks positive values of an eigenfunction, the eigenfunction has to already be positive for that system to ever be feasible.
Similarly, actual eigenfunctions cannot do anything but grow, shrink, or stay constant (even if pairs of eigenfunctions can oscillate). It’s actually worse than that: in the context of our universe, they can’t grow either. If we add a little coarseness to our observables to ignore things like thermal noise, the microstates describing heat death blur together, creating a fixed point or cycle where growing eigenfunctions would reach infinity. As these eigenfunctions cannot grow to infinity without being discontinuous, we'll only be dealing with .
Most functions describing the adherence to any behavior do not cleanly decay over time, so they are not eigenfunctions. For instance, the population of a species increases and then decreases, which is very poorly described by a single eigenfunction. Therefore, one would expect behaviors to only exist under certain ranges of eigenfunctions. One can imagine a sort of gate-like model, as shown below, but in reality, the connection could be messier.
The actual "adherence of a moral system" could be even more complicated to describe in terms of eigenfunctions. In general, its adherence could be cut off by multiple bounds and otherwise have weird non-linear descriptions composed of yet more eigenfunctions. I haven't even mentioned the sheer number of possible eigenfunctions to consider, including all of the symmetries that these eigenfunctions could have (rotational, translational, etc.) Some eigenfunctions may never even take on a significant value, making it impossible to properly realize them.
And finally, the spectrum (the list of eigenfunctions/eigenvalues) of the Koopman operator can turn into an uninterpretable mess if you process the data incorrectly.
My frustrations in trying to analyze the Hénon map
The Hénon map is one of the simplest chaotic dynamical systems, and an obvious test case for this discussion. It's defined by:
Concretely, this action bends the plane, contracts it, and then flips it. For certain values of a and b, this produces this strange attractor:
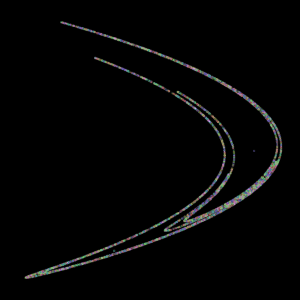
Despite the simple form of the map, its Koopman eigenfunctions are difficult to even find numerically, and they aren't all that insightful.
So, if finding Koopman eigenfunctions becomes incredibly complicated in the simplest of cases, how might we humans be at all able to wrap our heads around them? How is Koopman theory at all helpful?
Algorithms In Practice
Matrix Representations
As the Koopman operator is linear, we can represent it with a matrix mapping an observable to a linear combination of observables (another observable itself). We only need a basis of observables to construct the matrix.
So we want to find the high-eigenvalue eigenvectors of the matrix (i.e. "slow modes"). The easiest way to do so is by power iteration: just apply enough times, and eventually most of the faster modes would have decayed away, leaving you with your slowest modes. Funnily enough, the laws of physics are technically "using" power iteration to find slow Koopman eigenfunctions, but given how dense the eigenfunctions are, the algorithm doesn't converge in any reasonable amount of time.
What do we do, in comparison? When we actually slow down to make a decision, we take stock of several options and pick the best one. This happens to have a direct analogue in a certain type of observables.
These observables are closely correlated (albeit not exactly) with a number of simpler observables that make “hardcoded” choices. Perhaps these simple observables track agents that always choose a certain flavor of ice cream, for instance. These simpler observables vary along a few rows/columns in the representation of , representing slight differences in how they change state given some other observable. They also participate in slightly different modes with slightly different eigenvalues.
So these new observables just pick the response corresponding to the slowest mode. As such, by simply taking the argmax actions for the highest eigenvalues, they manage to beat almost all of these other modes. They also take less information to describe than a mode hardcoding the right actions, so they are more frequent. I will thus refer to the mechanism powering these modes as "argmaxxing."
Constructing Models
In this way, argmaxxing becomes a dominant strategy over time, eventually surpassing most of these simpler modes. So how might they function? For this to work in general, these argmaxxers must hold representations of small portions of to operate on; let’s call them “models.” For instance, they could hold a model as a matrix describing how various flavors of ice cream marginally affect brain functions within a short course of time.
Argmaxxers could do several things with these models, such as internally simulating power iteration, or alternatively, they could outright perform some kind of DMD on it to get a much more exact spectrum for the slowest modes. These results also help feed their own models: with sufficient sensory input, they can compare the predictions of their own models with reality's actual power iteration on . (If they expect raspberry ice cream to make them fnorp, but they instead flurp, they would accordingly change the numbers within the model’s matrix.) If a sufficient gap between their models and reality persists, argmaxxers can even increase the rank of their own models, tracking new observables in a way that improves accuracy.
Sharing Models
For the sake of argument, argmaxxers are physically-separate beings, each of which are short-lived. Argmaxxers manage to significantly align their models by finding ways to transmit observables and their approximations of , causing each argmaxxer to note possible discrepancies based on their own pre-existing models. Hashing through disagreements thus helps to ensure that models track reality. (Keeping with the ice cream example, argmaxxers that eat pistachio ice cream and argmaxxers that eat orange sherbet can compare observations and make larger theories.)
Over time, these argmaxxers set their own parameters, one by one, corresponding to what they've learned about . They encourage other argmaxxers to update their models over time, and they punish those that fail to follow them, hoping both to help bring them in line, but also to prevent another scenario. Certain observables describe resources that massively outweigh other factors in making certain modes eventually unsupportive of argmaxxing life (e.g. the quality of common areas). While these resources can be quickly consumed by fast-multiplying agents, those agents then trigger a die-off, taking many other argmaxxers with them. As such, it is of the utmost importance to prevent the existence of such "cancerous" agents. As each argmaxxer begins existence with a blank slate, they are taught pre-existing models through "stories" describing simplified past experience, helping to prevent them from being cancerous. (They may tell the story of the evil empire that forced everyone to only eat rocky road, even if they’re not aware of the resulting nutritional deficiencies leading to its downfall.)
The Inside View: Rectification
Through the learning process, interior experiences are easily created: argmaxxers may gain privileged access to observables describing the speed of various modes, and they are thus greatly rewarded. Argmaxxers thus use these observables to restrict their own behavior. As this process seemingly makes a mode feel "right," I dub it "rectification."
As a mode becomes more rectified in an argmaxxer's mind, the argmaxxer ties itself to the mode's mast: doing so may be helpful, but only if the mode was actually slow to begin with. So "good" argmaxxers rectify a mode if and only if such a mode is slow, or in other words, they only think something is good if it is sufficiently slow so as to not be selected against.
Argmaxxers are not, in general, humans, and for that matter, humans are only partially capable of argmaxxing in the first place. However, there do appear to be some parallels in some of our decision-making, and rectification likely plays a large role.
If rectification fully describes the moral arc of history, we can compress the aforementioned messy process of waiting for humanity to figure it out. So let's just skip to the end.
Skipping to the End
By definition, Koopman eigenfunctions need to precisely map back onto themselves with time. So if one of them measures the popularity of a specific moral system, it would have to measure an inescapable moral system. If we would expect some agents to change their moral behavior over time as one mode decays before the other, then eigenfunctions describing other moral systems must be non-zero. So a moral system exactly tracked by a mode must be fully rectified: all of the agents following it would have all of their volition accounted for. But, with this artificial, distilled ethics in hand, we get its eigenvalue and its half-life.
Here we glimpse the full power of the Koopman operator: it gives us a fully-defined metaethical standpoint. If you take your favorite ethics, define everything about it (including, say, what species it runs on and its starting population), and then type that into a supercomputer, you could get out an actual number corresponding to how long that ethics lasts! You can even simulate matches against your least favorite ethics! If you used your simulation to pit the two systems against each other (while forcing all humans to follow one or the other), you could see which contains the eigenfunction with the longest half-life.
Even better: if your simulated humans undergo rectification like we would expect, they'll learn to verbalize arguments for the winning moral system! So in fact, your simulations can concoct "people" that arbitrarily endorse the most adaptive ethics for your simulation.
So I propose the following general algorithm for making the best decisions:
- Find the slowest eigenfunctions of the Koopman operator of reality w.r.t. the list of decisions
- Figure out which of them are significantly realizable in hypothetical, yet attainable future states
- Attain said states
- Wait for the faster eigenfunctions corresponding to different decisions to no longer take on any noticeable value
- Everyone agrees with you!
The best part is that reality—by virtue of the construction—has been slowly converging to similar slow eigenfunctions. So we did it! We solved morality.
If you believe the above argument, you can radically simplify most philosophical lines of inquiry! I'm going to save those thoughts for a later post, but this frame could be a very useful tool for cutting through tradeoffs and vague definitions. For instance, it could be used to analyze the alignment problem, Knightian uncertainty, metaphilosophy, word definitions, decision theory, CEV, correlates of consciousness, emotions, and government structures. These posts practically write themselves.
Caveats
But that's a massive "if." First of all, how much should you trust someone who isn't even 20 to formulate a new type of metaethics based around mathematics that they only learned four months ago from Claude Opus 4.8? My interpretations of these eigenfunctions are debatable, and it's possible that I've gone into a happy death spiral in trying to think of anything useful to write here.
For that matter, remember to not roll your own metaethics (i.e. don't use this in practice immediately), and I would be really careful about using this to justify much of anything right now. In particular, it seems like my argument could be called upon to justify anything without anyone being able to check. And make sure to keep this timeless wisdom in mind:
To me, the clearest and strongest objection is that humans probably wouldn't like the highest-eigenvalue eigenfunctions of reality. If you caught my very subtle foreshadowing, you realized that "skipping to the end" just means causing the heat death of the universe. Besides that, though, the next-slowest modes are also undesirable.
While some AI apocalypse scenarios could be quite wasteful and entropic, ASIs would be much more capable of finding, implementing, and maintaining very slow modes for trillions of years. Even if paperclip-maximizers were conscientious enough to not make a black hole and destroy themselves with their paperclips, and even if they managed to hone in on the best morality through beautiful intellectual debate and romance or something, I expect that you don’t want that. Similarly, you probably don't want to be overtaken by the Super-Happy people or the hedonium shockwave, even if they're on a slower eigenfunction and outlast everything you value.
A slow mode could also be a major s-risk, like an infinite authoritarian space regime that tortures babies for its own persistence. The only thing that might make you feel even slightly better about these possible s-risks is that they'll eventually become highly rectified: remember, rectification occurs to a mode if and only if such a mode is slow. That is, if suffering is meant to be something that makes a being disengage with an activity, but that activity is somehow part of a very slow mode, then the being might have to fully engage eventually. Maybe that ends the suffering? I could also note that Monsters,-Inc.-style universes seem more entropic than harmonious universes, which makes it less likely that s-risks are very slow. However, both of these rebuttals only work on a longer scale, and the situation doesn't leave a great taste in one's mouth.
So let me add something to the algorithm above:
- Find the slowest eigenfunctions of the Koopman operator of reality w.r.t. the list of decisions
- Figure out which of them are significantly realizable in hypothetical, yet attainable future states
- Apply an arbitrary filter, only leaving behind regions that make humanity happy
- Attain said states
- Wait for the faster eigenfunctions corresponding to different decisions to no longer take on any noticeable value
- Everyone agrees with you!
The impurity might not make Beff Jezos happy, but it should lead to fewer repugnant conclusions.
As for what the arbitrary filter could be, I might suggest that you search for states containing at least a certain degree of rectification: that is, you should look for eigenfunctions that require argmaxxers of “a certain degree” to maintain it. Filters don't avoid the Super-Happy people problem, but there's not much of an obvious separation between banning Super-Happy people, banning transhumanism, and banning trans rights. Likewise, you could filter for some shared memory of the value of humanity to ensure that these eigenfunctions contain our descendants. These filters may not solve other problems you might see in the world either (e.g. wildlife suffering, inequality), so you could continue refining them.
However, any filter you apply could remove the slowest possible modes. That is, your moral preferences may have an early expiration date. If you're lucky, such a date could be quadrillions of years away, but I might suggest coming to terms with it eventually.
Mottes/Conclusion
Everything above is speculative, but I do hope it’s useful to someone, even if it needs some work. If the genealogy of morality or the Koopman operator frame fails, I think I can still argue that:
- Finding and reaching stable equilibria by making robust models is a good idea
- You can use or iterate on relatively well-established mathematical techniques to achieve (1)
- (1) is probably the explanation for a lot of our morality
- Consider long-term variables before disregarding (3) in specific cases
- Keep the expiration date of your morals in mind
- By the way, donate to neuroscience. Do you realize how much easier equilibrium calculations and dynamical control would be if we had a better grasp of cognition and human behavior? If you take (1) seriously, understanding the brain is a severely neglected cause area.
So you could nudge your efforts towards stabler outcomes. Maybe you could calculate at least one eigenfunction.
Thanks to @Joe Carlsmith, @Wei Dai, @RogerDearnaley (underrated!), and many other essays pointing in this direction for inspiring me. Thanks to for telling me about Koopman theory in the first place. Thanks to @Jo Jiao and @Noah Birnbaum for talking with me as I developed these ideas, and finally, thanks to my brother, Claude Opus 5, @aspiringLich, and Adrien Amouroux for reviewing drafts.
- More rigorously, one would want to atomize values into specific behaviors following a value in certain situations. In that case, the main assumption needed is still that such a behavior wasn't followed in the past.
- If you want to read further into moral constructivism/naturalism arguments based on natural selection, I would recommend reading up on Sharon Street's Darwinian Dilemma, Joe Carlsmith's works on metaethics, as well as this discussion by Steven Byrnes. Sharon Street especially argues for moral constructivism this way more rigorously.I would also be interested in discussing with critics (like L Rudolf L) to find cruxes!
- A reviewer mentioned that what I'm describing occurs in a lower-tech form in polygynous groups, which seem stable-ish, so there may be ways to make widespread sperm bank usage work. Technically, if the qualification process was robust enough, the Goodharting wouldn't occur?
- (LaTeX works weirdly in footnotes: click to go down.) It's linear because . This proof mainly relies on function addition distributing across composition.
- It's actually the adjoint of the Koopman operator.
- Quantum mechanics/relativity makes eigenfunctions even more challenging to interpret, so I'm going to take the principled decision to ignore it.
- The subset of a dynamical system corresponding to zeroes of an eigenfunction is a "separatrix," which is a very nice word and I thought you should know
- If our observables can explain literally everything, then as the universe allows for closed Hamiltonian systems, a lot of eigenvalues would lie on the unit circle. Most of these would describe useless, high-entropy particle configurations. There still wouldn't be any continuous growing eigenfunctions.
- These eigenfunctions could also depend on the environment the agents are in!
- I should mention that there are other algorithms (PCCA+ looks promising) that also find the spectra of dynamical systems. One can also map Koopman eigenfunctions onto almost-invariant regions of phase space; really, there's many other operators/methods that achieve the same effect as the Koopman operator. Still, there is quite a lot of theoretical dynamics work to do if one was going to, say, simulate the universe with these, so please don't dismember me in the comments for picking Koopman here for simplicity's sake. Relatedly, I do need to read the surrounding literature, but I was hoping to finally get this out so as to have a nonzero impact (given timelines these days). This was also eating my mind up for ~two years. If I'm decisively proven wrong in the comments, that would be wonderful; I could finally think about something else.
- It is officially the least efficient algorithm currently running, using all of the universe’s available compute.
- They do take a small penalty for taking time/energy to calculate the eigenfunctions.
- Notably, my construal of "argmaxxing" seems close to a crux between Yudkowsky and I, which might explain what he finds wrong with my argument. He refutes me clearly in The Gift We Give to Tomorrow:
Evolution has nothing like the intelligence or the precision required to exactly quine its goal system.
I wonder if such a point is required for him to reject the moral constructivism above, as he does through the rest of the sequences. - That is, one could tell that the eigenfunction is non-zero. This makes the most sense when thinking about quasi-stationary distributions, which are Markov processes that eventually reach an absorbing set, but may take a long time to do so.These absorbing sets do correspond to eigenfunctions in the form of telescoping sequences of absorbing sets. If measurement tools are then unable to detect the difference between the current absorbing set and the intersection of all such absorbing sets, then one could say that the eigenfunction is zero. Absorbing sets probably also handle issues like quantum mechanics more accurately, but the exposition is less clear.
- It's possible that a slow mode would still be selected against before a fast mode if the slow mode was very weak to begin with. However, in the case of moral systems, if most argmaxxers can adopt any moral system with sufficient justification, the "potential" for all of them start out ~identically, so this technicality usually doesn't apply.
- By the way, I hazily recall a moderator commenting that one should not try and write a theory of metaethics for one's first LW post, to whom I apologize if they are reading this. (The second paragraph of footnote 10 applies here, though.)
- I've also read Fake Utility Functions; the complexity of the slowest eigenfunctions should encapsulate the complexity of "real" utility functions, so the main thrust of the post doesn't apply. Of course, I have little idea as to if I've found my belief's weakest links, although I try below.
- At the very least, one should make a matrix-based model with determinant less than or equal to 1, but one should also provide a set of initial conditions to actually show that the eigenfunction they advocate for is attainable. This is a far slower process than making an internet comment, unfortunately, but teams of experts could become proficient at constructing models.
- Transhumanism wouldn't necessarily encroach on the rights of others to exist as they please, but subtler, long-term selection events do seem likely to eventually cause the remnants of humanity to switch over.
- It's also possible I've been entirely scooped somewhere that I haven't found yet. If so, please tell me! I didn't see anything similar in the LW embedding search, however.I do keep stumbling on posts that get scarily close to hitting on the main idea, however, such as No Strong Orthogonality From Selection Pressure and Substrate Needs Convergence. And also everything @RogerDearnaley has written for the past two years.

 点赞
 收藏
 点踩
 分享