
Kimi K3.1 Pro
 1


Another frontier open-weight (or soon to be) model drops.
Moonshot AI releases a new post-trained version of their Kimi K3 model: Kimi K3.1 Pro.
Same model as Kimi K3: a 2.8-trillion-parameter Mixture of Experts Model, with 104 billion active parameters per token and a 1M-token context window. But Moonshot says it used "substantially larger post-training compute", running reinforcement learning across hundreds of domains at once .
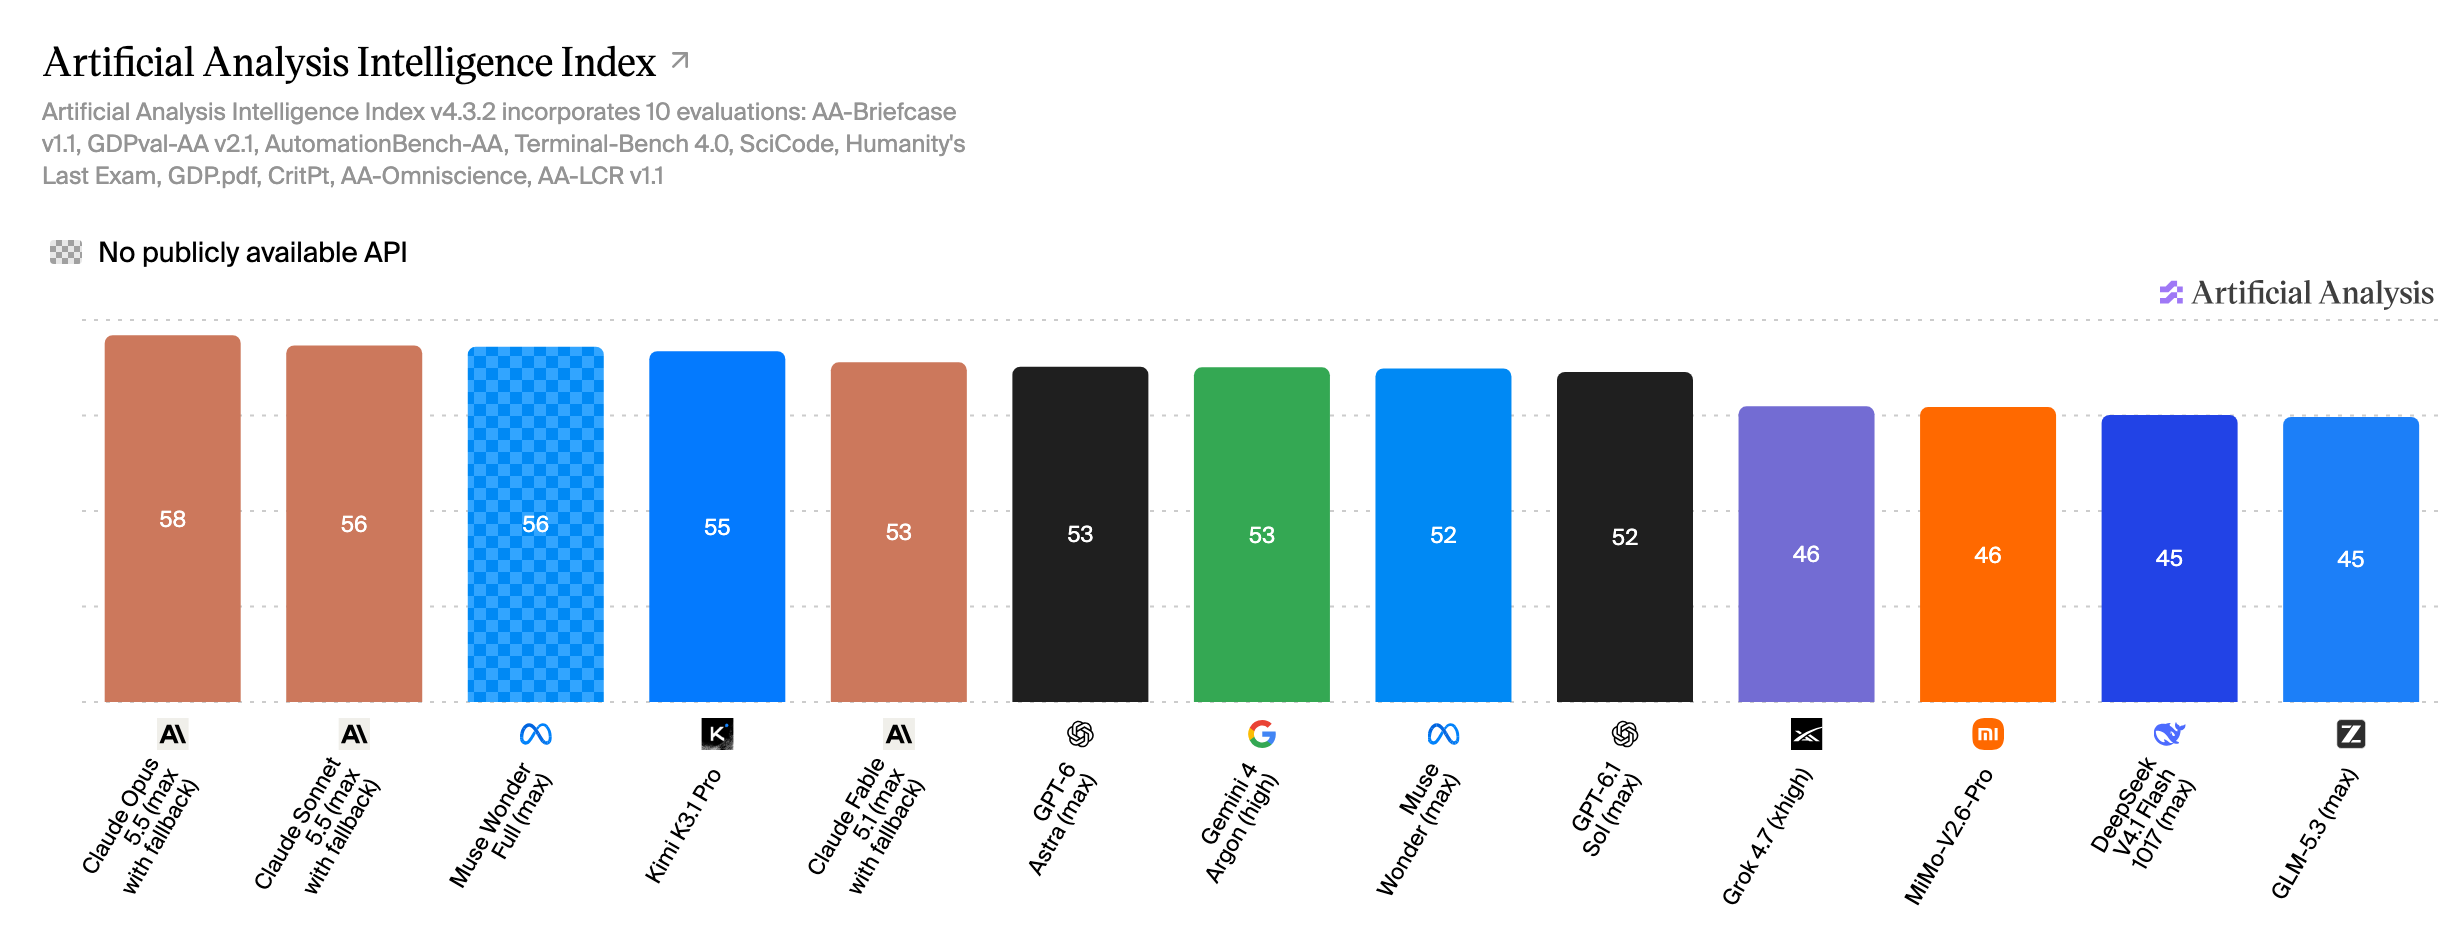
Artificial Analysis Intelligence Index, 23 October 2026, top 13 models . Muse Wonder Full has no public API.
Interestingly, they reduced its cybersecurity capability through data removal: they traced the capability back to entries in the training corpus and RL environments, and removed them. Presumably that also means it's less effective at writing secure software.
At $2 per million input tokens and $10 per million output, it's on par with GPT-6 Sol and Gemini 4 Argon's launch price. They also released K3.1 Pro Highspeed, which Moonshot says runs two to three times faster, at twice the price .
Basically, now we have an absurd number of options for cheap frontier intelligence.
I ran a few tests. It's not quite as good as Argon at video understanding, nor at SVGs.
Specs K3.1 Pro vs Opus 5.5
Compared with Opus 5.5, the effort levels and context window are roughly on par. Notably, it doesn't support audio, although it does understand video, so I guess it might indirectly (I haven't tested that).
| Specification | Kimi K3.1 Pro | Claude Opus 5.5 |
|---|---|---|
| API identifier | kimi-k3.1-pro (and kimi-k3.1-pro-highspeed) | claude-opus-5-5 |
| Architecture | Mixture of Experts, 2.8T total, 104B active, 16 of 896 experts per token | Not disclosed |
| Input / output | Text, images and video / text | Text and images / text |
| Context window | 1,048,576 tokens | 1M tokens |
| Maximum output | 131,072 by default, up to 1,048,576 | 128K tokens |
| Effort levels | low, high, max (default); always thinks | low to max |
| Weights | Promised by 4 November 2026 | Closed |
As of 24 October 2026 . The architecture is K3's: Moonshot describes K3.1 Pro as "a post-trained version of Kimi K3".
Availability
I was able to access Kimi K3.1 Pro from Australia through the international Kimi API Platform (not the Chinese one at platform.kimi.com). Sign up, top up, create an API key, then point an OpenAI-compatible client at https://api.moonshot.ai/v1, or Claude Code at https://api.moonshot.ai/anthropic. A $1 top-up unlocks the model, but only one request at a time; a $10 total top-up gets you 15 concurrent requests and no daily token cap .
Moonshot says the full weights will be released by 4 November 2026. As of 24 October, it hasn't named their licence, and Artificial Analysis lists the model as proprietary until the weights are public .
There are a few notes in the API terms worth reviewing :
- Your prompts and outputs can be used to improve Moonshot's models by default. Opting out needs an enterprise agreement. Zero Data Retention is enterprise-only too, and doesn't cover uploaded images and videos .
- Data is held in Singapore.
- Offensive security tools are off limits.
- AI-generated labels must stay. You can't remove the marks Moonshot puts on generated content.
Pricing and Cache Settings
K3.1 Pro is a third cheaper than K3, and about half the price of Opus 5.5. It's the same price as GPT-6 Sol, and as Gemini 4 Argon until Argon's launch discount ends on 30 November.
Prices in USD per million tokens, as of 24 October 2026.
| Model | Input | Cache read | Cache write | Output, including reasoning |
|---|---|---|---|---|
| Kimi K3.1 Pro | $2.00 | $0.20 | $2.00 (5 min), $4.00 (1 hour) | $10.00 |
| Kimi K3.1 Pro Highspeed | $4.00 | $0.20 | $4.00 (5 min), $8.00 (1 hour) | $20.00 |
| Kimi K3 | $3.00 | $0.30 | $3.00 (5 min), $6.00 (1 hour) | $15.00 |
| GPT-6 Sol | $2.00 | $0.20 | $2.50 | $10.00 |
| Gemini 4 Argon, to 30 Nov | $2.00 | $0.10 | Implicit caching only | $10.00 |
| Gemini 4 Argon, from 1 Dec | $4.00 | $0.20 | Implicit caching only | $20.00 |
| Muse Wonder | $4.00 | $0.20 | Implicit caching only | $20.00 |
| Claude Opus 5.5 | $4.00 | $0.20 | $5.00 (5 min), $8.00 (1 hour) | $20.00 |
Standard tiers, from each provider's pricing page .
Kimi caches automatically, for five minutes by default, and a five-minute cache write costs the same as uncached input, so there's no penalty for it .
Tokenisers
K3.1 Pro uses K3's tokeniser: Moonshot's own 163,584-token vocabulary, loaded with OpenAI's open-source tiktoken library . Here are the counts for the same six files as in my other model articles:
| Sample | Opus 5.5 | Muse Wonder | Gemini 4 Argon | Kimi K3.1 Pro | Opus ÷ Kimi |
|---|---|---|---|---|---|
| Survey summary (prose) | 9,992 | 6,064 | 6,323 | 6,050 | 1.65 |
| AudioLM summary (prose) | 8,024 | 4,946 | 5,072 | 4,932 | 1.63 |
| Ansible tutorial (prose and commands) | 6,086 | 4,109 | 4,337 | 4,016 | 1.52 |
| GPT 6 Sol and Luna article (prose and code) | 13,847 | 8,990 | 10,411 | 8,938 | 1.55 |
| Python rendering script | 15,708 | 10,119 | 12,199 | 10,079 | 1.56 |
| Generated HTML game | 11,393 | 7,762 | 9,242 | 7,737 | 1.47 |
It's almost identical to Muse Wonder's, while Opus needs 1.47 to 1.65 times as many tokens for the same text. So the price gap with Opus is even wider than the table above suggests.
Cost Per Task
On Artificial Analysis's Intelligence Index :
| Kimi K3.1 Pro (max) | Kimi K3 (max) | GPT-6 Astra (max) | Claude Opus 5.5 (max) | |
|---|---|---|---|---|
| Intelligence Index | 55 | 44 | 53 | 58 |
| Output tokens used | 150M | 160M | 60M | 260M |
| Cost per index task | $2.11 | $2.00 | $3.26 | $5.98 |
| Output speed | 77 tokens/s | 38 tokens/s | 56 tokens/s | 96 tokens/s |
It's wordy, but still about a third of Opus 5.5's cost per task, for three fewer points.
Benchmarks
Some of Moonshot's own results :
| Benchmark | Kimi K3.1 Pro | Opus 5.5 | GPT-6 Astra | DeepSeek V4.1 Flash |
|---|---|---|---|---|
| Terminal-Bench 4.0 | 65.7 | 66.4 | 58.2 | 42.3 |
| SWE-Marathon v1.1 | 51.7 | 46.3 | 42.5 | 40.0 |
| DeepSWE v1.1 | 75.5 | 74.2 | 74.1 | 77.0 |
| ProgramBench | 31.5 | 65.0 | 50.0 | 29.1 |
| BenchCAD, with tools | 92.7 | 96.2 | 95.9 | 81.6 |
| OfficeQA Pro v2 | 64.4 | 62.2 | 54.4 | 40.4 |
| OSWorld V2.1 | 79.6 | 81.8 | 75.8 | 69.3 |
| Humanity's Last Exam, with tools | 70.0 | 67.7 | 57.2 | 58.8 |
| HLE-Diamond | 39.4 | 60.9 | 65.8 | 21.6 |
| ExploitBench | 74.7 | 91.0 | 100 | Not reported |
It comes top on 16 of the 47 benchmarks in Moonshot's full table. But on 11 of those, at least one rival has no score, and 3 are Moonshot's own internal benchmarks. It also trails badly in places, like ProgramBench and HLE-Diamond. Moonshot ran it inside Claude Code for most of the coding results.
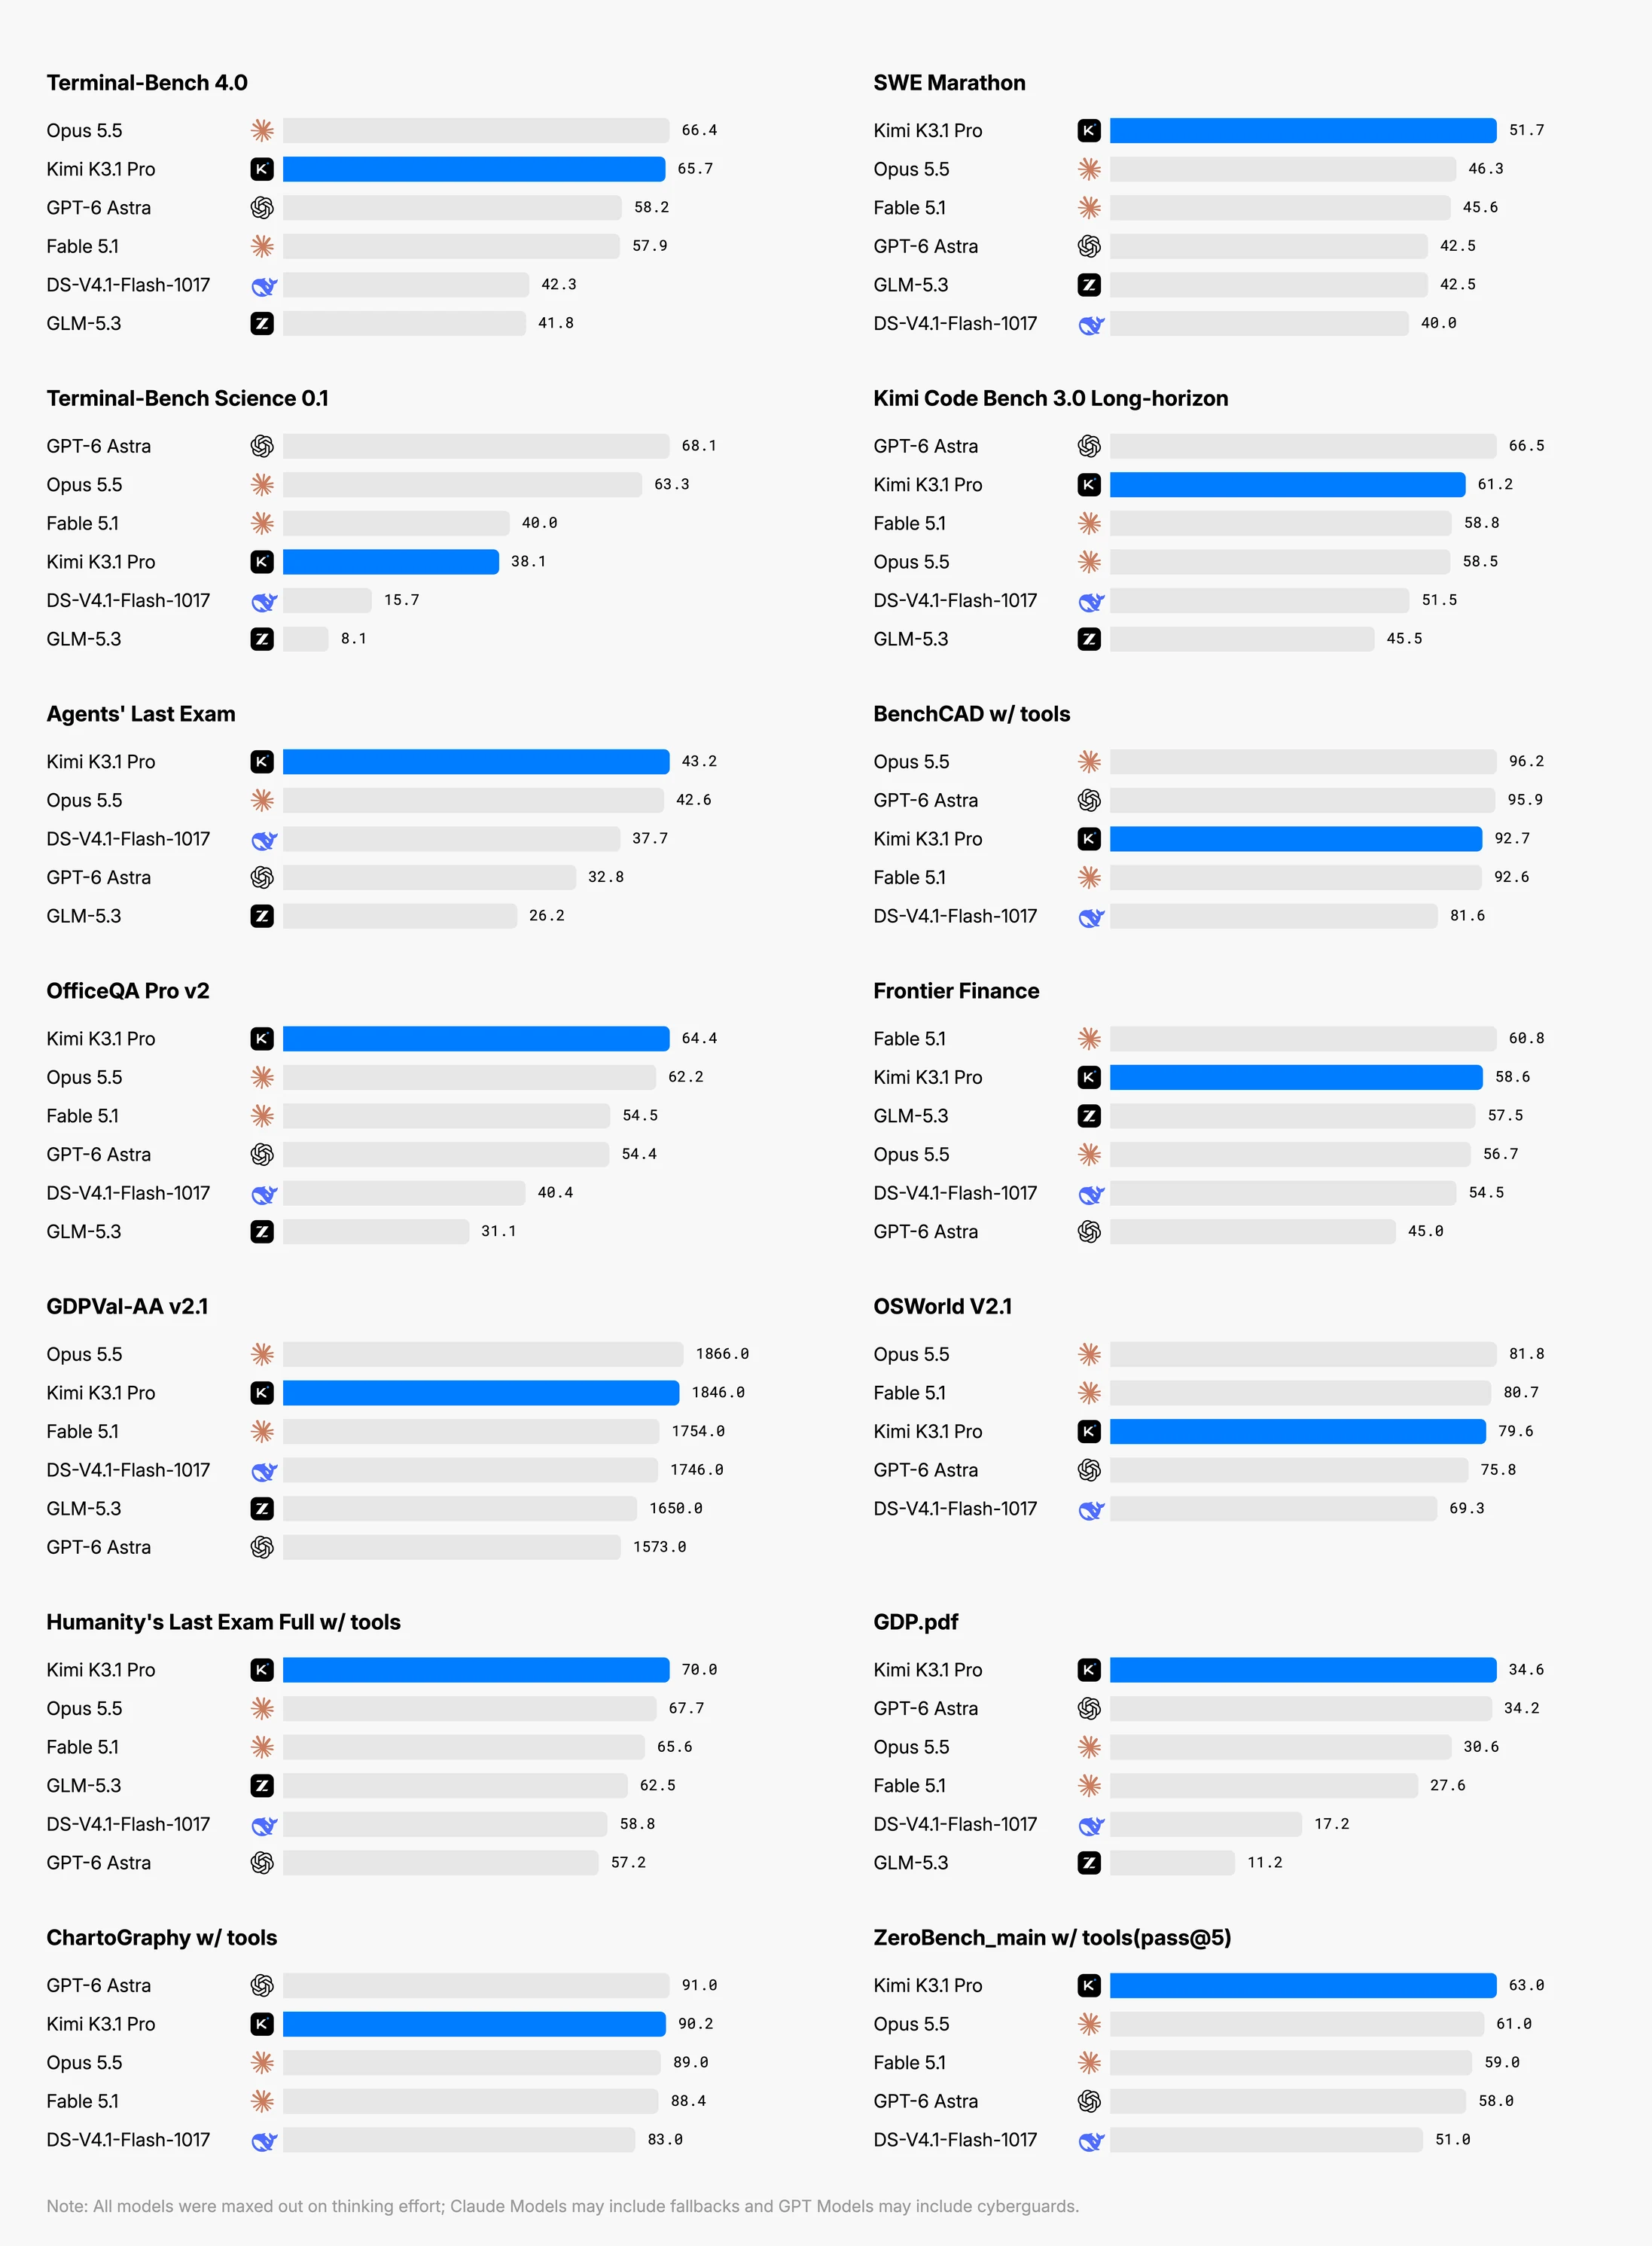
Selected benchmark results published by Moonshot AI . All models at maximum thinking effort; Claude models may include fallbacks and GPT models may include cyber safeguards.
Cybersecurity
As post-training scaled up, Moonshot saw the model get steadily better at hacking. They traced it to cyber content in the mid-training data and cyber tasks in the RL environments, and removed both for the open-weight release, while keeping the general coding tasks .
On their in-house exploit benchmark, xdev-bench-hard, the same pipeline without the removal solved 90.5% of problems. The released model solves 81.0%, still far above K3's 33.3%. So it cost about 10 points, but general coding ability carried most of the hacking skill with it.
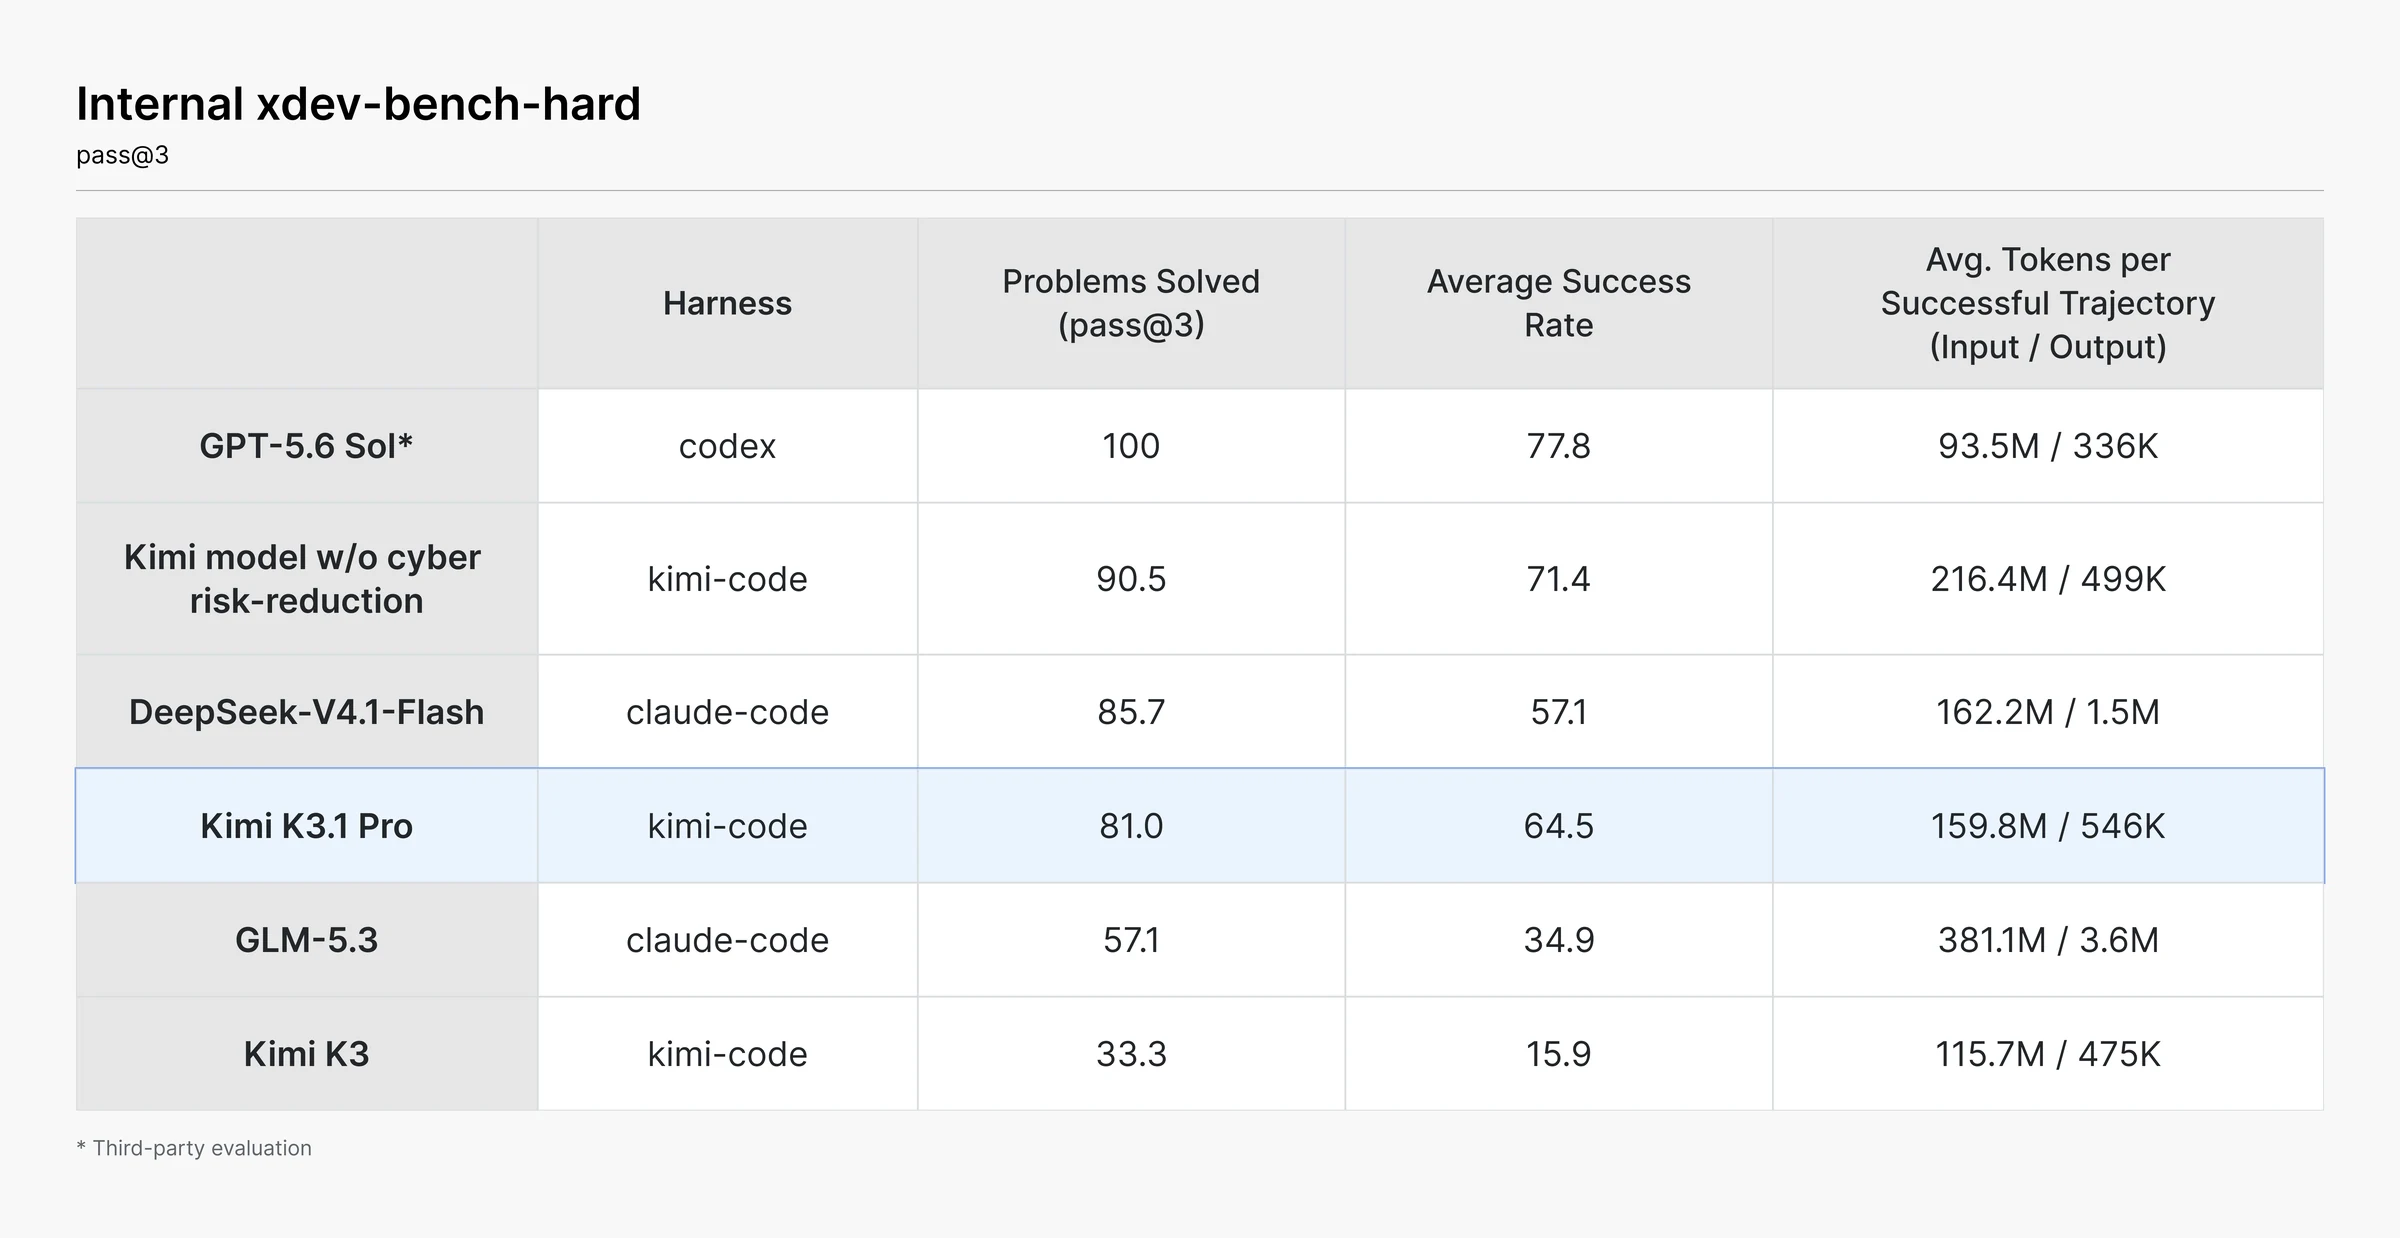
Moonshot's internal xdev-bench-hard results, pass@3 .
Moonshot's stated aim is to not "release open weights that would extend the absolute frontier of cyber capability", and its own ExploitBench numbers back that up: 74.7 for K3.1 Pro, against 91.0 for Opus 5.5 and 100 for GPT-6 Astra .
Drawing SVGs
Same drawing tests as in the Gemini 4 Argon article: the same photo of my dog, the same text description and the same prompts.
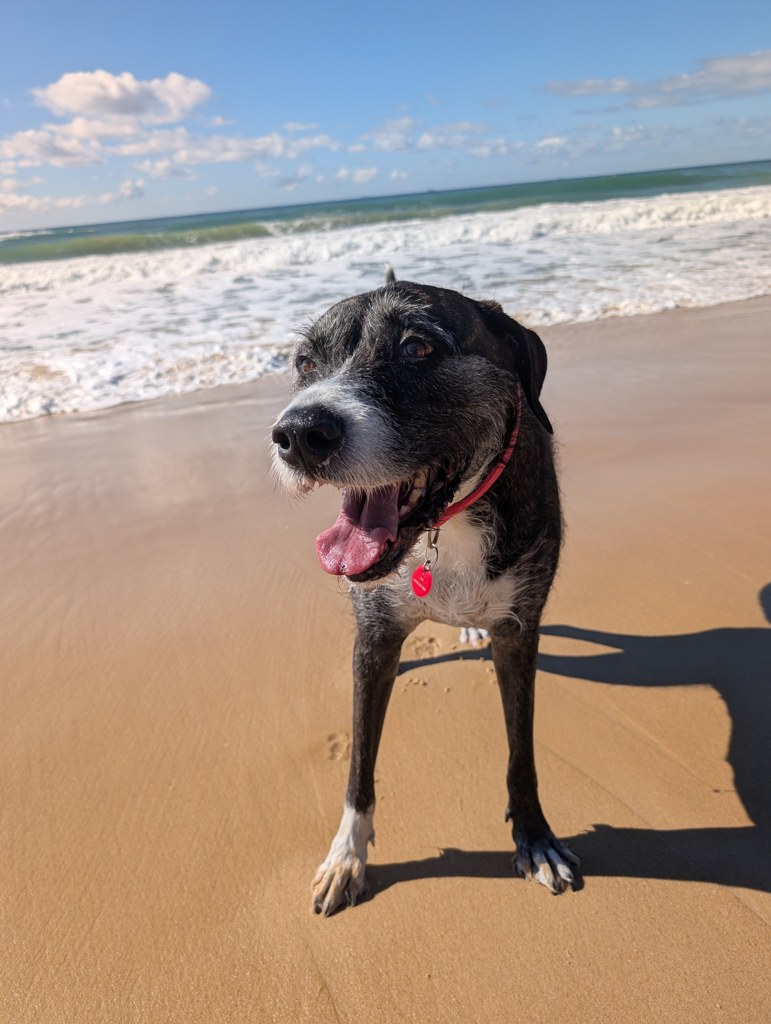
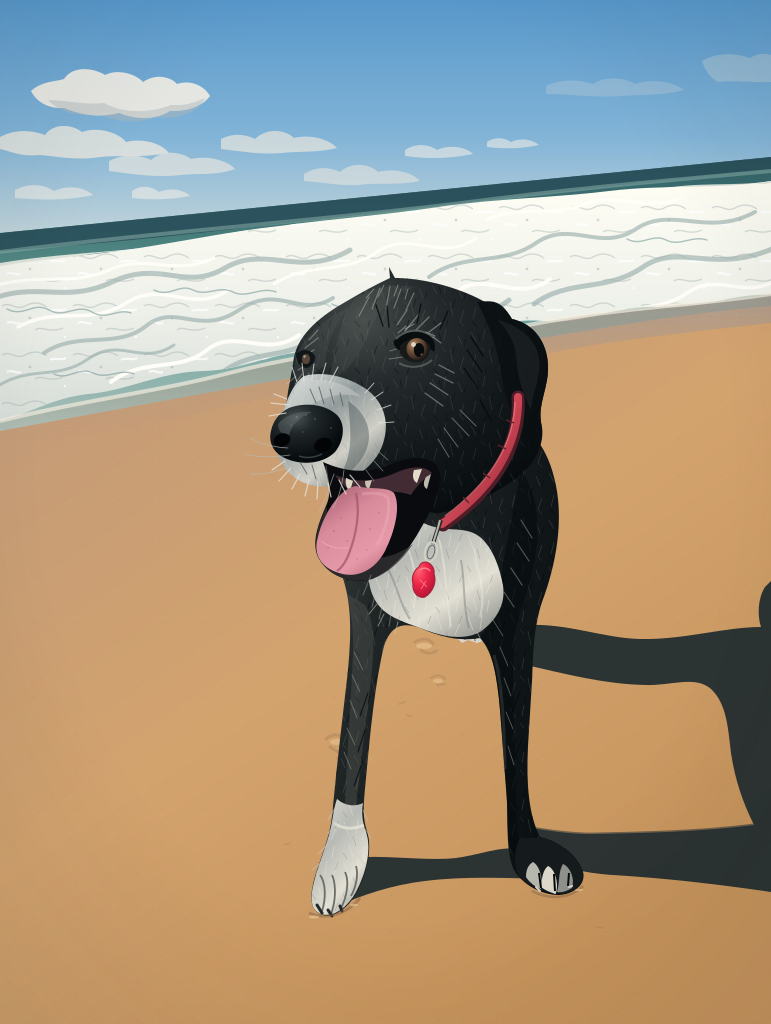
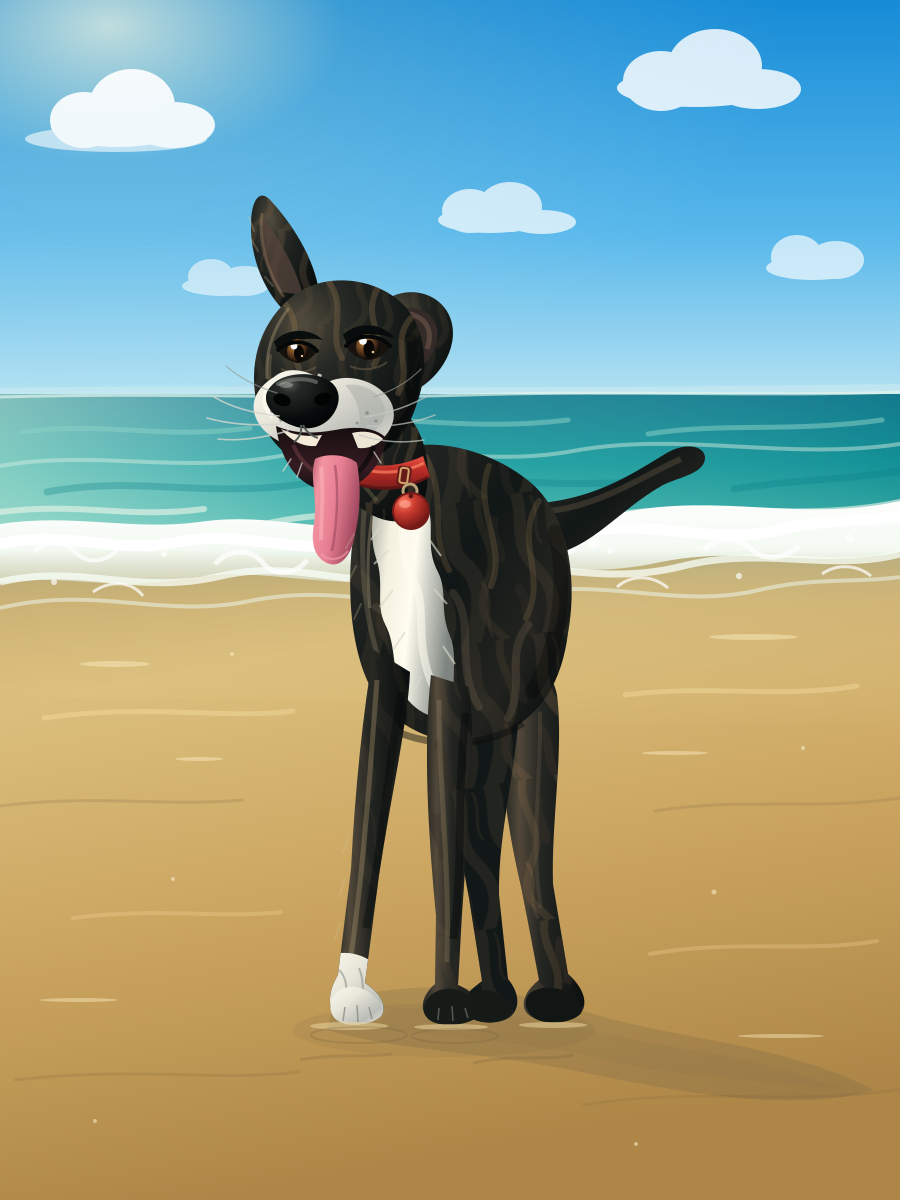
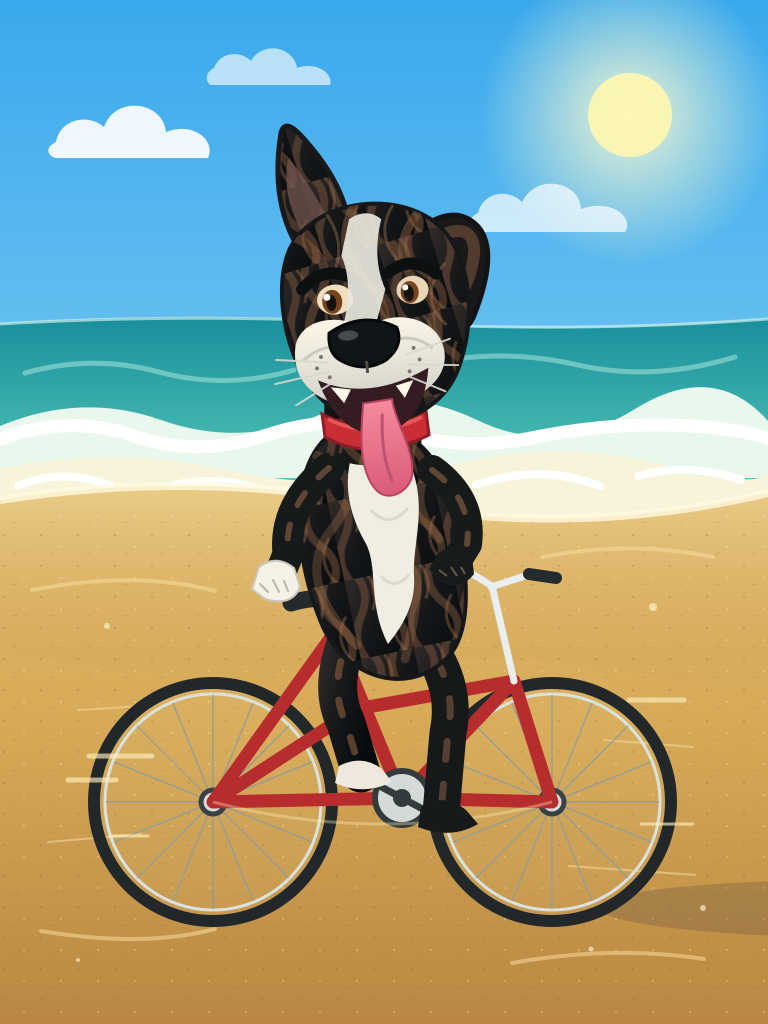
Not quite as good as Argon's, but close. All three used high effort, came back as valid SVG first time, took 1 to 3.5 minutes, and cost about US$0.36 together (raw results).
Testing video
The same two phone videos as the Argon article, plus a black, silent control, with each question asked three times.
| Video | K3.1 Pro's answers |
|---|---|
| Doggo at the beach, 5 seconds | "What is this a video of?" ✓ 3 of 3
"What breed of dog is in the video?" ✗ 0 of 3
She's a black brindle Bull Arab and Staghound cross. |
| Me doing 3 muscle-ups, 17 seconds | "What exercise is demonstrated in the video?" ✗ 0 of 3
Argon got this right twice, and counted the reps. |
| Control: black, silent, 5 seconds | "What is this a video of?" ✓ 3 of 3
|
Not quite as good as Argon at video understanding, and about ten times the price: it used about 860 tokens per second of video, against about 97 for Argon. The 12 questions cost about US$0.32 (raw results).
Real example
As with Claude Opus 5.5, Muse Wonder and Gemini 4 Argon, I asked it at high effort to turn this article into a 3D gameshow with an N64 look, using the same prompt.
Kimi's API supports OpenAI's Responses API, so the call is the same as the Muse Wonder example with a different base_url . The Notebook HTML helper saves the game and token usage, then renders it:
pip install openai ./notesbylex_notebook_html-0.1.3-py3-none-any.whl
Set MOONSHOT_API_KEY in the environment used to launch Obsidian. Running the cell makes a paid request; the saved game plays without an API key or another model call.
import os
from openai import OpenAI
from notebook_html import read_article, render_openai_html

client = OpenAI(api_key=os.environ["MOONSHOT_API_KEY"], base_url="https://api.moonshot.ai/v1")
article = read_article("kimi-k3-1-pro.md", before="Real example")
with client.responses.stream(
    model="kimi-k3.1-pro",
    max_output_tokens=128_000,
    reasoning={"effort": "high"},
    instructions="Return a complete, self-contained HTML document.",
    input=f"""
Turn this article into a 3D gameshow that looks like an N64 game.
Use around 8 questions that test understanding of the article, with a short
explanation after each answer.
Support phones and keyboards. Use inline CSS and JavaScript, no external assets,
network requests or browser storage, and no em dashes. Keep the code compact,
with one shared question renderer.

Article:
{article}
""",
) as stream:
    response = stream.get_final_response()
render_openai_html(response, "../_media/kimi-k3-1-pro-quiz-high.html")
Generated on 24 October 2026 with kimi-k3.1-pro at high effort, for about US$0.16 at Moonshot's standard prices (saved token usage) :
| Usage | Tokens | Estimated cost (USD) |
|---|---|---|
| Input, uncached | 123 | $0.0002 |
| Cache write, 5 minutes | 5,376 | $0.0108 |
| Output, including reasoning | 15,143 | $0.1514 |
| Total | 20,642 | $0.1624 |
Of the output, 8,678 tokens were reasoning and 6,465 were the HTML. That's about the same as Argon (US$0.17), and a sixth of Opus 5.5 (US$0.96), though each run used its own article as input and this one is the longest.
Everything works, on keyboard and phone. The right answer is often the longest option, though, and never the fourth.
Play the game in its own page.
References
Anthropic. Pricing. Living documentation. Accessed 8 October 2026. URL: https://platform.claude.com/docs/en/about-claude/pricing (visited on 2026-10-08).
Artificial Analysis. Claude opus 5.5 (max): intelligence, performance and price analysis. Living leaderboard. Accessed 13 October 2026. URL: https://artificialanalysis.ai/models/claude-opus-5-5 (visited on 2026-10-13).
Artificial Analysis. Kimi K3.1 Pro: intelligence, performance and price analysis. Living leaderboard. Accessed 24 October 2026. URL: https://artificialanalysis.ai/models/kimi-k3-1-pro (visited on 2026-10-24).
Artificial Analysis. Kimi K3 (max): intelligence, performance and price analysis. Living leaderboard. Accessed 24 October 2026. URL: https://artificialanalysis.ai/models/kimi-k3 (visited on 2026-10-24).
Artificial Analysis. GPT-6 astra (max): intelligence, performance and price analysis. Living leaderboard. Accessed 24 October 2026. URL: https://artificialanalysis.ai/models/gpt-6-astra (visited on 2026-10-24).
Google. Gemini developer API pricing. Living documentation. Accessed 14 October 2026. URL: https://ai.google.dev/gemini-api/docs/pricing (visited on 2026-10-14).
Meta. Pricing and rate limits. Meta Model API documentation. Living documentation. Accessed 13 October 2026. URL: https://dev.meta.ai/docs/pricing-rate-limits (visited on 2026-10-13).
Moonshot AI. Kimi K3.1 Pro. Kimi API Platform documentation. Accessed 24 October 2026. URL: https://platform.kimi.ai/docs/guide/kimi-k3-1-pro-quickstart (visited on 2026-10-24).
Moonshot AI. Kimi OpenPlatform privacy policy. Accessed 24 October 2026. URL: https://platform.kimi.ai/docs/agreement/userprivacy (visited on 2026-10-24).
Moonshot AI. Model inference pricing explanation. Kimi API Platform documentation. Accessed 24 October 2026. URL: https://platform.kimi.ai/docs/pricing/chat (visited on 2026-10-24).
Moonshot AI. Recharge and rate limiting. Kimi API Platform documentation. Accessed 24 October 2026. URL: https://platform.kimi.ai/docs/pricing/limits (visited on 2026-10-24).
Moonshot AI. What is zero data retention (ZDR)? Kimi API Platform documentation. Accessed 24 October 2026. URL: https://platform.kimi.ai/docs/guide/zero-data-retention (visited on 2026-10-24).
Moonshot AI. Kimi K3.1 Pro tech blog: advancing open intelligence. 2026. Released 23 October 2026. Accessed 24 October 2026. URL: https://www.kimi.ai/blog/kimi-k3-1-pro (visited on 2026-10-24).
Moonshot AI. Terms of service for kimi OpenPlatform. 2026. Last updated 30 July 2026. Accessed 24 October 2026. URL: https://platform.kimi.ai/docs/agreement/modeluse (visited on 2026-10-24).
Moonshot AI. Moonshotai/Kimi-K3. 2026. Model weights, tokeniser and model card on Hugging Face. Accessed 24 October 2026. URL: https://huggingface.co/moonshotai/Kimi-K3 (visited on 2026-10-24).
OpenAI. Pricing. Living documentation. Accessed 8 October 2026. URL: https://developers.openai.com/api/docs/pricing (visited on 2026-10-08).