ML4Good Impact Assessment

Intro
At ML4Good, we run annual follow-up surveys to keep track of what people are doing and to measure our impact.
In late 2025, we sent our alumni survey to 340 alumni, 223 of whom responded. Of those, 135 are now doing something in AI safety, adding up to about 98 full-time equivalents (FTE).
After estimating outcomes for the people who didn't reply, we think that around 186 of the 340 (~55%) are doing something in AI safety, or ~147 FTE. Based on what alumni told us about ML4Good's counterfactual impact, we estimate that ~77 FTE were counterfactual - these people would not be spending their time on AI safety absent ML4Good. Like others in the field, we find counterfactual impact hard to measure, so we're less confident in this figure than in the others. We also have over 200 recent alumni from 2026 bootcamps that we haven't yet followed up with.
We’re reporting all of our costs for the evaluation period openly, and we make an estimate of how cost-effectively we get people into AI Safety work. We calculated a “fully-loaded” cost of £5.4k per FTE, or £9.3k per counterfactual FTE produced.
We’re publishing our data and letting other field-builders know our best guess at how many people are working in AI safety as a result of ML4Good, and at what cost. We’ll also give some caveats and uncertainties about our results, and a bottom line estimate of our impact, given all considerations.
Summary of activities
As of October 2026, there will have been 31 ML4Good bootcamps across 12 countries since August 2022. Over this period, we’ve trained around 600 alumni.
We initially focused on technical bootcamps. After becoming an organisation in early 2025, we scaled up our operations to run 9 bootcamps last year, and developed a new Governance & Strategy curriculum, before scaling to 12 a year in 2026.
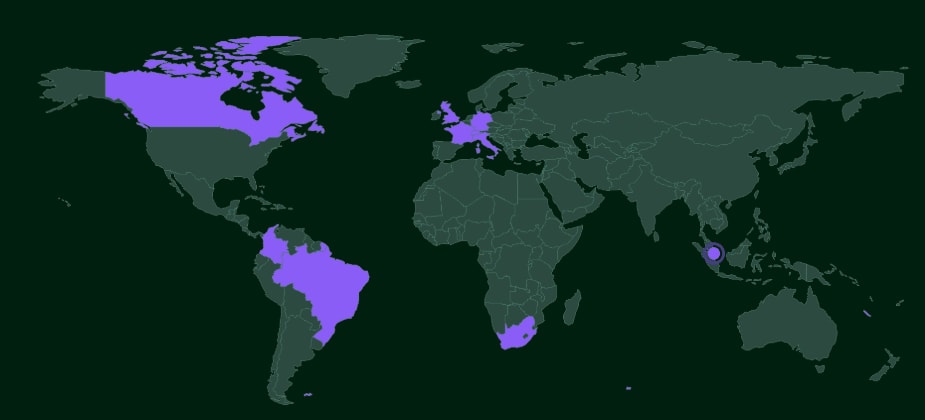
We've operated in the highlighted countries.
What this impact assessment covers
Our impact assessment covers 17 bootcamps (340 participants), including 13 from Europe (inc. UK), 3 in Latin America, and 1 in Asia.
We haven’t yet run our latest round of alumni surveys, therefore only our bootcamps up until the end of September 2025 were included in this analysis. All except one were technical bootcamps. It also doesn’t include two bootcamps run in 2023 with SafeAI Lausanne in Switzerland, which used slightly differing surveying strategies.
Community building as an indirect result of ML4Good has also caused many more people to engage with or contribute to AI safety. However, we don’t have concrete numbers on this and chose not to include this in our evaluation.
Summary of results
Our bootcamps have been successful at achieving our objectives of getting more people working in AI safety.
- An estimated 186 alumni are now working in AI Safety in some capacity (~55% of all participants), or the equivalent of 147 FTE.
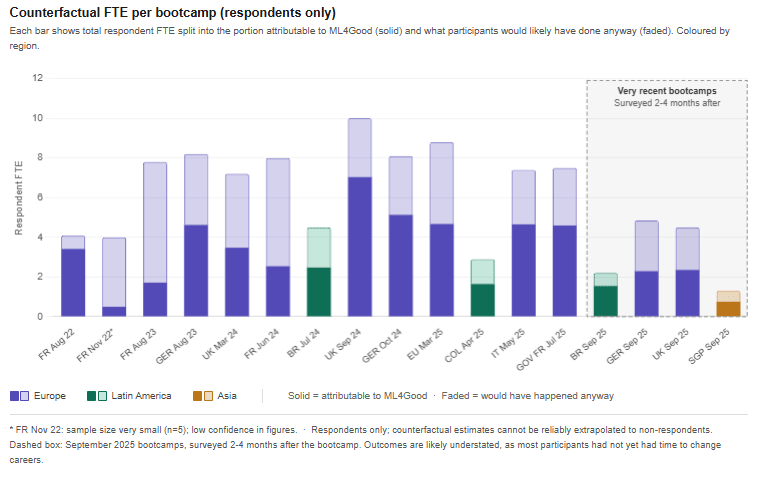
- Many of these participants consider our bootcamp the main reason they're currently working in AI safety. Based on self-reported counterfactuals, we estimate that around 77 of those 147 FTE would not have happened without ML4Good.
- Several alumni-founded communities have been developed as a direct result of ML4Good.
- We receive strongly positive feedback from all of our bootcamps, and 98% of participants recommend ML4Good.
- There are many caveats and uncertainties, especially around how we attempt to measure counterfactual impact, so we want to be transparent about this.
What we try to do
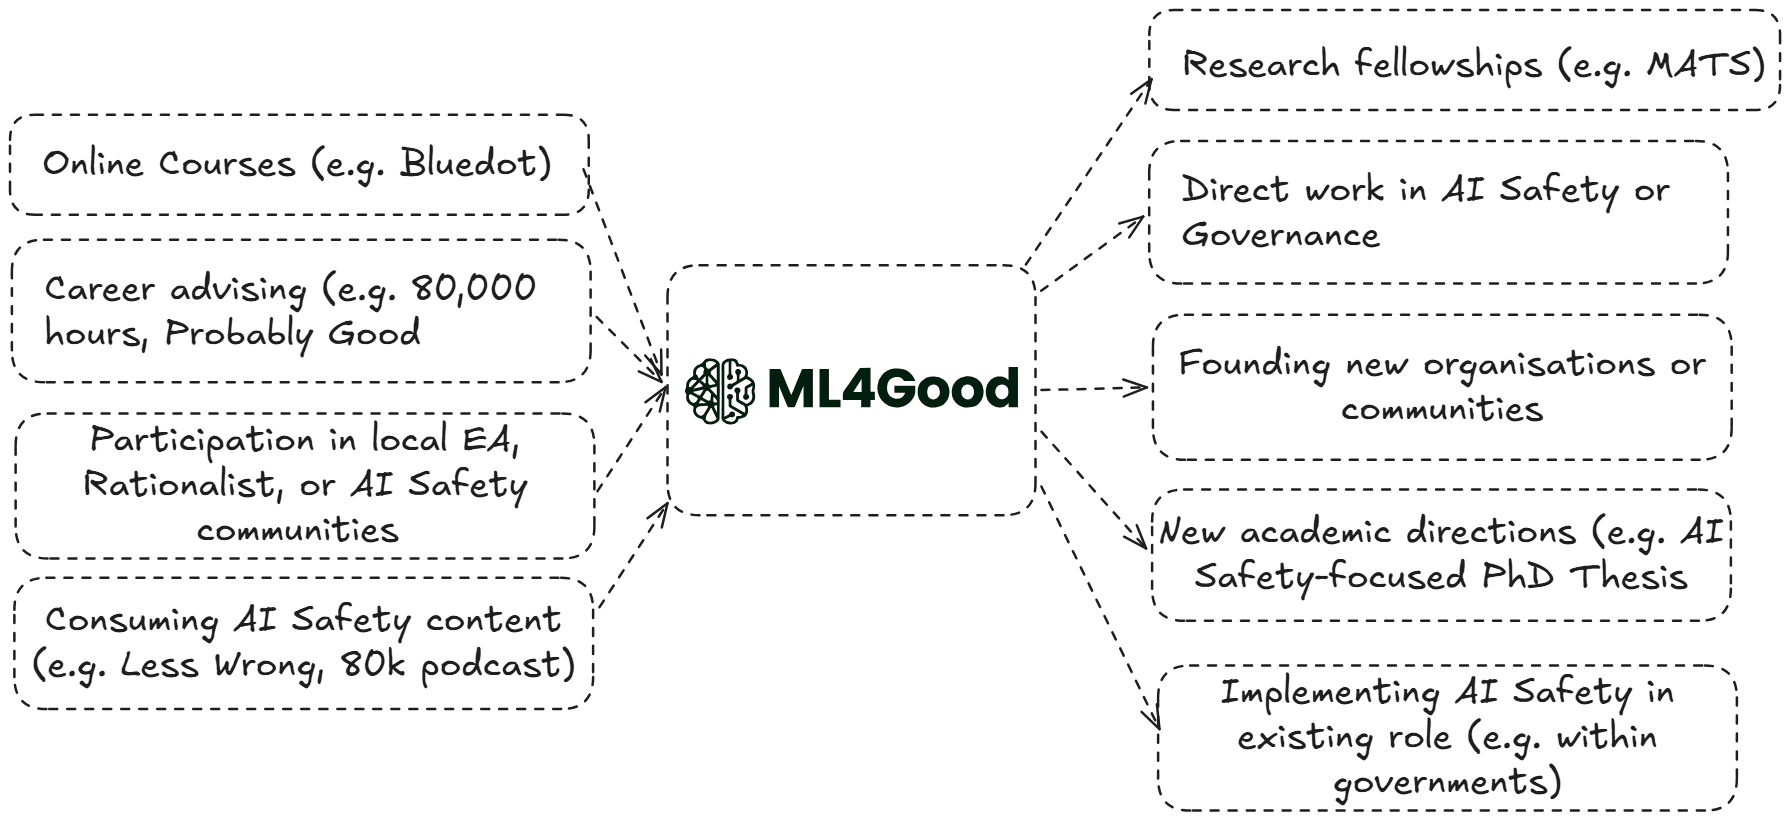
ML4Good plays a role fairly high up the funnel in the AI safety talent pipeline. Our focus is on providing a transition point for people thinking seriously about a move into AI Safety. We're relatively selective - in 2026, we accepted around 15% of applicants. We usually target people who have engaged with entry level content, such as BlueDot, online technical safety courses, or reading the relevant literature, e.g. LessWrong/EA forum/80,000 Hours content, but who have usually not yet committed to a concrete path.
After ML4Good, we encourage and support alumni to take future steps to contribute to AI safety. Some alumni start targeted research programmes like MATS, Pivotal, SPAR, ERA, and Talos. Others enter direct roles in AI Safety, conduct independent work, or found new organisations. Some find ways to integrate AI safety into their current work, which can be promising, particularly for our alumni working in policy and law.
Over 8 days, we create a motivating in-person environment where participants are guided by inspiring teachers and surrounded by other participants with similar goals. We aim to empower attendees to think ambitiously about how to have an impact, to act with high agency, and to find whereabouts in AI safety they are best suited to contribute. They spend the final days of the bootcamp making and starting to implement concrete plans.
While most of our bootcamps run in Europe, we have also succeeded in identifying and supporting talented people across five continents, often in areas with limited AI safety ecosystems. Our strongest outcomes are in Europe, where many of our alumni have gone on to form important parts of the AI Safety ecosystem. Our earlier bootcamps mostly attracted people with technical backgrounds, but, with our expansion beyond technical programmes, we’re now broadening our reach to people from diverse professional backgrounds, and generalists.
Outcomes
To track outcomes, we send follow-up surveys to alumni. We aim to survey people about 6 months after their bootcamp and then once a year after that.
This survey data gives us a picture of what our alumni are working on. We use this primarily as evidence to adjust our approaches – to see where things are going well and to check whether our bootcamps are having the intended impact.
We ask what difference the bootcamp made to them, what actions they took as a direct result of the bootcamps, what they’ve been up to since, what they’re doing now, further AI Safety programmes they’ve done (e.g. MATS, ARENA), and the counterfactual impact that ML4Good has had. See the survey here for our specific questions.
From our last surveys in August and November 2025, we had a 66% response rate (223 of 340 participants).
To see whether the profiles of responders and non-responders would differ significantly, we tracked non-respondent outcomes via LinkedIn for 3 bootcamps to assess whether non-respondents are less likely to engage in AI Safety post-bootcamp. Non-respondents had a very slightly lower engagement in AI safety on average.
We then extrapolated from this estimate with a correction factor applied to estimate outcomes for all 340 participants. Our full methodology, including how we scored FTE and counterfactual impact, and how we extrapolated to non-respondents, is in Appendix 2.
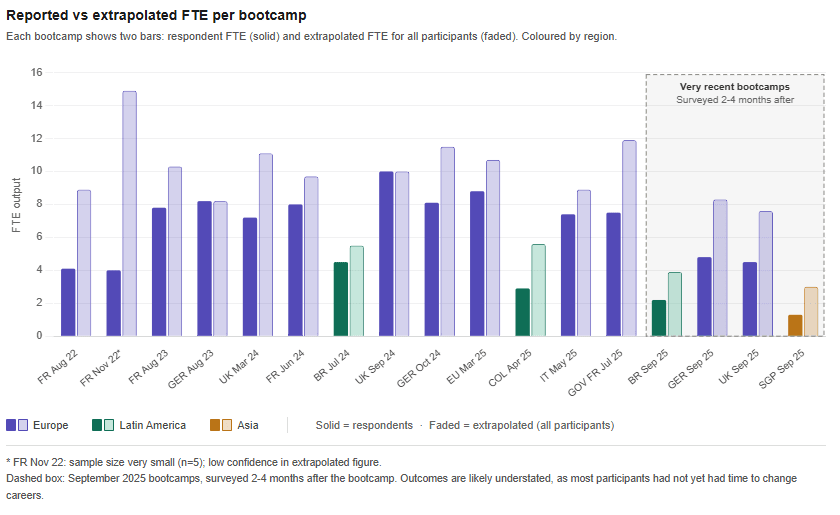
The table below illustrates what people are doing after ML4Good. We’re very confident in the baseline figures for how many ML4Good alumni are doing something in AI Safety. Our confidence is lower for both counterfactual impact and extrapolated information for non-respondents.
Participant outcomes span a range of roles and engagement levels. This is the distribution of reported positions from respondents:
- 55 were pursuing further AI safety programmes, including MATS, ARENA, SPAR, LASR, Talos, Pivotal, MARS, ERA, ARBOx, AI Safety Camp and GovAI fellowships, at the time of surveying. This is the most common next step for participants.
- 14 in direct technical AI safety roles
- Alumni mention roles at Timaeus, the London Initiative for Safe AI, and independent work funded by Coefficient Giving.
- 15 in direct governance roles
- Positions include the EU AI Office, CeSIA, the Observatorio de Riesgos Catastróficos Globales, and GovAI
- 6 in AI safety entrepreneurship
- Our alumni have had founding roles at several major European AI Safety orgs
- 7 doing PhDs in AI safety, and an additional 13 have written or are writing PhD or Masters theses on AI safety topics
- 10 in independent AI safety research
- 17 in professional field-building, 25 in voluntary fieldbuilding (e.g. running university groups)
- At least 12 AI safety communities have been founded by alumni, including:
- Buenos Aires AI Safety Hub, Argentina’s first AI safety community, founded in July 2024.
- 350+ community members, 15-person volunteer leadership team, 6 full-time AI Safety roles
- Runs official BlueDot Technical AI Safety cohorts
- AISAR research fellowship: 6 scholars, 3 ICLR workshop papers
- Developing MATSx Buenos Aires with Ryan Kidd advising
- AI Safety Saarland - launched October 2025 with a 300+ attendee event featuring an Anthropic safety team speaker.
- Runs two fellowships: intro course (30 participants) and research incubator (14 mentors, 33 mentees)
- Holds regular public events including an Apart def/acc hackathon hub (50 attendees)
- Has ~100 regularly engaged members within three months
- Founder has joined with Safe AI Germany to scale the incubator nationally
- AI Safety Bulgaria, AI Safety Mexico, AI Safety Colombia, Lisbon AI Safety Hub
- Buenos Aires AI Safety Hub, Argentina’s first AI safety community, founded in July 2024.
- At least 12 AI safety communities have been founded by alumni, including:
There were no obvious patterns as to whether people doing more ambitious things attributed more or less of their impact to our bootcamps.
Several of our highly successful alumni attribute an over-95% counterfactual impact to ML4Good. To cherry-pick a few exceptional examples, this category includes an early alumnus who is now an AI security researcher at a Paris-based AI policy organisation, an AI governance fellow at a European think tank, the founder of a highly successful field-building programme in Germany, and someone building the technical infrastructure for model evals with the EU AI Office.
A much higher number (89 alumni) report an over-50% counterfactual impact. These include a 2024 alumnus who took part in a research fellowship, led a nine-month independent project and is now a control researcher at a leading AI safety organisation, a 2025 alumnus moving into a technical role at an EU body that enforces rules on the algorithms and AI systems used by large platforms, and a research manager at MATS.
As well as these career changes, our alumni generally give positive qualitative feedback about the bootcamps and how ML4Good has impacted their careers. Some of these answers strongly indicate counterfactual impact, such as mentioning targeting roles or fellowships that they applied for during the bootcamp, or as a direct consequence of ML4Good.
As well as nudging people towards working in AI safety, it also helped some people already committed to AI Safety to refine their plans, clarify their theory of change, or try something more ambitious. For example, some realised that they were a better fit for non-technical or founding work.
Negative responses were rare. Out of 206 people who answered these questions, 8 alumni mentioned downsides - feeling more burned out, overwhelmed or more anxious about AI risks. 2 people mentioned that ML4Good made them realise that AI safety wasn't a good fit for them. 11 alumni mentioned applying for things that they didn't get into, and 6 mentioned that they would have taken similar actions without the camp.
Differences between bootcamps
Our bootcamps all follow a similar structure and curriculum, but there is variation in terms of teachers, participants, location, and timing. There are many different variables, so it's difficult to come to strong conclusions about what works and what doesn't.
In terms of direct FTE working in AI safety, our strongest outcomes so far have been in Europe. This is probably for two reasons:
- Europe’s relatively mature AI safety ecosystem gives alumni clear pathways into roles; and
- The underlying pool of people exposed to AI safety ideas is a lot larger than the other regions we’ve covered, so we’ve been able to select slightly stronger participants
The data from Latin America shows fewer direct career transitions, but our bootcamps there have driven strong community-building outcomes, including the founding of AI Safety hubs in Argentina, Colombia and Mexico, which have in turn attracted new people to AI safety. In newer communities, alumni often have to build the path first by starting groups, making connections, and securing funding. Many of the people now working on AI safety in Latin America have a connection to our bootcamps, either as alumni or through the hubs alumni founded. There is also far less AI Safety activity in Latin America, meaning that more of our impact is likely to be counterfactual.
All things considered, while we opted not to do any in 2026, our bootcamps in Latin America were promising enough to merit further bootcamps in the region in 2027.
We collected survey data on Singapore very soon after the bootcamp in 2025; although a few people had already made career transitions directly, and attributed some of this to ML4Good, we expect that this year’s follow-up survey will capture more accurate data.
We ran bootcamps in Canada and South Africa earlier in 2026, and will run one in Hong Kong in late October 2026. Survey data from these bootcamps will inform whether we intend to go to different countries and regions next year.
Cost-effectiveness
We’ve always taken cost-effectiveness very seriously, and, from our 2025 estimates, our bootcamps run at roughly £1,850 ($2440) per participant, including overhead and off-season costs.
For context, EAGx events, which are shorter, non-residential, and not designed to provide active training, cost around £430 ($570) per attendee; EA Globals cost £630–£1,855 ($834-$2460) per person. While we don’t have much information about the running costs of other field-building programmes in AI safety, ML4Good bootcamps run more cheaply than most long-term residential fellowships that provide accommodation in urban centres, salaries, and significant compute costs.
A naive extrapolation of our cost-effectiveness looks like £5.4k per FTE, or £9.3k per counterfactual FTE produced, calculated from £473,553 spent across bootcamps covered by previous funding, divided by 87 FTE and 51 counterfactual FTE from those specific bootcamps.
Caveats
We want to be very open about our uncertainties.
Is “more people working in AI Safety” the right metric?
The FTE scoring is not a standardised metric, and is only meant as a proxy for meaningful AI safety work. There are a few reasons that this might not be the ideal metric:
- It counts all work equally. The impact of people working full-time on entry-level fellowships is not directly comparable to those who have founded or run orgs. An attempt to quantify would probably find that founding a major org in the AI safety ecosystem is orders of magnitude more impactful than someone joining a research fellowship. Even within research fellowships or organisations being founded, some of these are more likely to reduce existential and catastrophic risk than others. We initially tried to score what people were doing on this axis, but we decided it would add too many arbitrary decisions to the model.
- Not all AI Safety work is clearly positive. Although we do not appear to have any alumni working for frontier labs, or on dangerous capabilities, some of our alumni may be doing AI Safety research that is making AI-related catastrophic harm more likely.
- It’s timing-sensitive. Our metric only captures a snapshot of whether people are spending their time on AI safety at the time of response, and not whether they are working in stable full-time work. Over multiple years "Is working on AI safety at any given time" becomes a good proxy for full-time work, but less so for a single snapshot a few months after a bootcamp.
- Goodhart's law says that when a metric becomes a target, it stops being a good metric. Counterfactual FTE metrics are still only a proxy for reduction of catastrophic and existential risk. We don't optimise hard for these metrics, so this doesn't seem a significant risk, but it could reduce trust from skeptical observers.
Overall, we do think this metric captures what we want to do in a way that allows us to compare across bootcamps. We expect that the impact of our alumni is non-linear, and this heavy tail is less well captured by our quantitative metrics. For this reason, we also look at our alumni qualitatively.
Shouldn’t we have more rigorous counterfactuals?
Laura Thomas-Walters’ piece on “Do AI Safety Talent Programmes Work? Nobody has run the study that would tell us” correctly notes that AI Safety Talent Programmes haven’t been great at determining counterfactual impact, or at least reporting this impact publicly. We also haven’t met the gold standard for determining counterfactual impact with either random or quasi-random methods.
We rely on two questions:
- "What are you doing now?"
- "Please put a number to ML4Good’s impact between 0-1. (If you think you would definitely not have taken these actions and be doing what you are doing now without attending ML4Good, put 1. If you think there is a 50% chance, put 0.5.)"
The first is fairly reliable and easy to verify, the second much less so. Estimating a counterfactual is hard, and we suspect that self-reported answers are more likely to lean in the direction of exaggerating the impact of ML4Good, because of social desirability bias/participants wanting to credit a programme they enjoyed. We adjusted down answers that seemed overstated, but this only partly fixes the problem, and we expect some residual exaggeration.
There is also a risk of double counting. Many alumni went through several programmes that all played a part in their getting into AI safety. For example, someone might have had an 80,000 Hours advising call, done a BlueDot course, and attended ML4Good, and needed all three to end up in AI safety. Assuming complete honesty and accuracy, they could all reasonably claim “but-for” causality (there would be no chance I would be in AI safety without all three), but if each programme counted that person as a full counterfactual FTE, the field as a whole would count one person three times. This is a problem because we don’t distinguish between ML4Good playing the sole role vs. being a small but essential part of a larger causal chain.
Finally, given the fact that the AI safety movement has been rapidly growing since 2023, some of these people might also have found their way into AI safety within a year or two anyway.
Rather than attempting to quantify how we might adjust the counterfactual impact for these factors, we’d suggest using the below figure to estimate costs per counterfactual FTE using different assumptions.
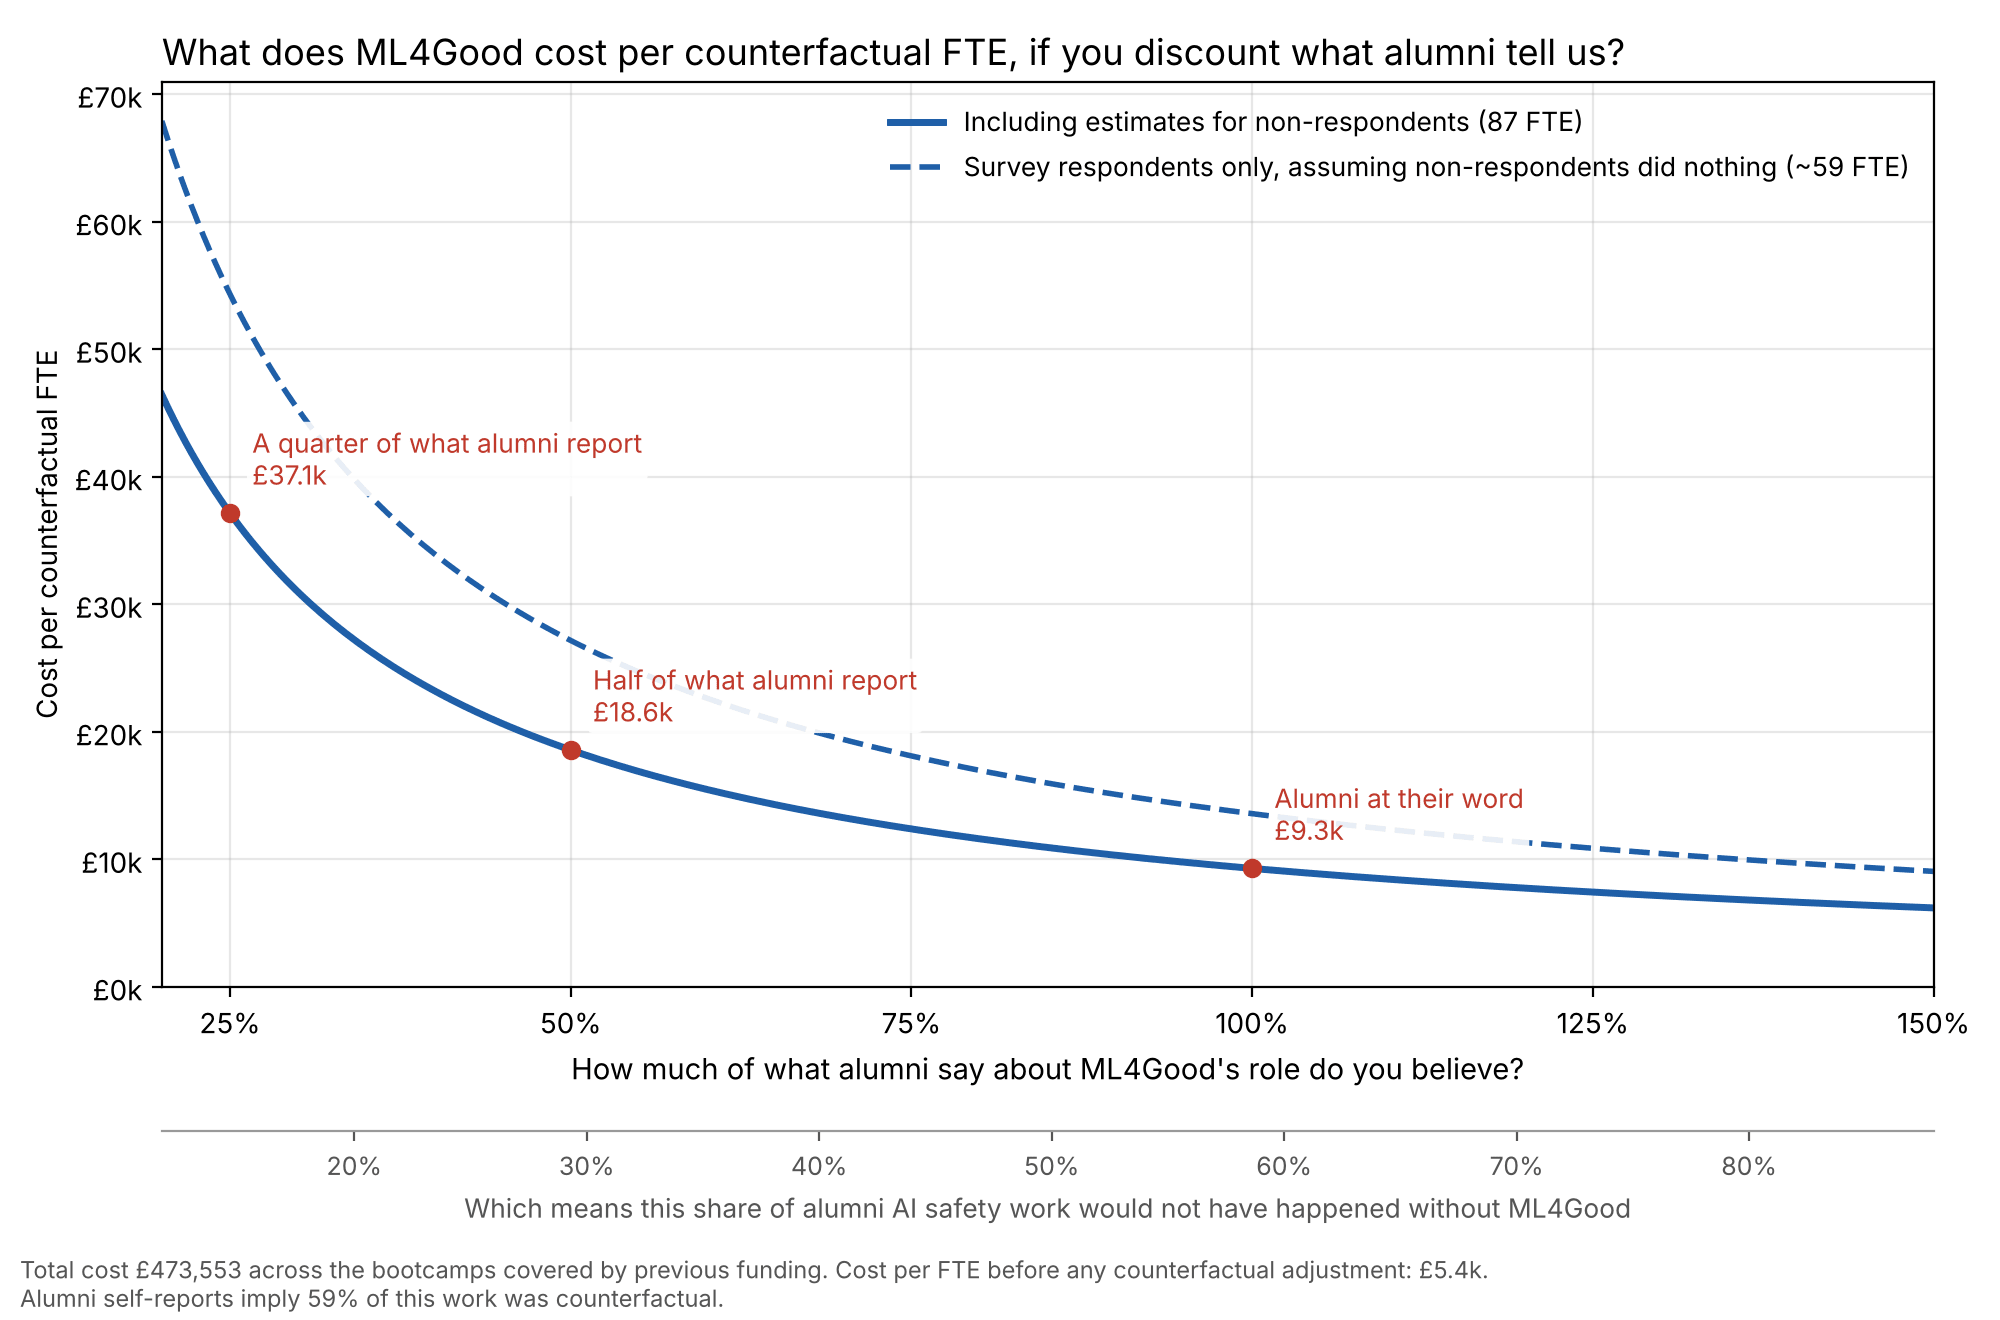
Ideally, we would like to use more careful statistical methods to track our counterfactual impact. Laura Thomas-Walters’ piece suggested using methods like regression discontinuity with rejected applicants or non-attendees. It’s uncertain whether the methods suggested in the piece mentioned above would work with our data, as ML4Good hasn’t always had the merits of being “massively oversubscribed and the cutoff for being accepted [being] relatively arbitrary”, such that we would have a pool of “near misses”.
However, we would like to track non-attendees in future, and plan to contact:
- People who dropped out due to unrelated factors, for example illness or visa problems, to compare their trajectory to those who attended
- This is likely to be around 50 people across all bootcamps
- Near-miss participants, from our waitlist of 6-7 participants for each recent bootcamp
- This is likely to be around 100-150 people in total
While we’d expect this group to have a lower survey response rate, even if numbers were too low for a statistically significant comparison set, it could at least provide some useful reference data.
How comparable is cost-effectiveness across interventions?
We think we've done things cost-effectively, both in terms of outputs (putting people through bootcamps) and outcomes (getting people into AI Safety roles). But it's difficult to make comparisons across interventions for a couple of reasons:
- Some organisations haven't released information on how much their programmes cost, therefore it's hard to judge the cost per participant, let alone the cost per positive outcome.
- Different points in the pipeline have different priorities and considerations. For example, research-based programmes produce valuable research alongside getting people into full-time safety work. It may also be easier/cheaper to enable people to take earlier steps towards a competitive fellowship vs. later steps towards a full-time role.
Either way, we hope that our costs-per-participant data might be useful to other organisations as a baseline.
Bottom Line
Our survey results increase our confidence that ML4Good is a cost-effective intervention with promising evidence for counterfactual impact. We've managed to keep strong relationships with a lot of our alumni, and we've seen how participants have directly gone on to productive AI safety work as a result of the bootcamp, and it's great to see that our data supports this.
Next Steps
We commit to posting our latest survey results by the end of 2026 once we have completed our annual survey.
We will use the same methodology and have preregistered the approach we will use here.
Expect an update soon on our plans for the next year!
Thanks so much to all of our alumni for responding to our survey, and thanks to Charbel-Raphaël Segerie and Diego Dorn for their feedback on drafts of this post.
Appendix
Appendix 1: How we have spent money
From Jan to Dec 2025:
Appendix 2: Impact Assessment Methodology
To estimate the impact of ML4Good bootcamps on participants' careers in AI safety, we used follow-up surveys, combined with some manual research on LinkedIn, and extrapolated our survey results for non-respondents. This is a brief overview of how we did this:
Surveys
We sent two rounds of follow-up surveys to bootcamp alumni. The first, in August 2025, covered bootcamps up to March 2025. The second, in November–December 2025, covered bootcamps up to September 2025 and also followed up with non-respondents from the first round. Both surveys included a counterfactual question: in the first, respondents were asked to describe what difference ML4Good made in their career and how much of their subsequent involvement in AI safety was a result of attending ML4Good, rather than something they would have done anyway. In the second, as well as this qualitative question, respondents were asked to put a number from 0 to 1 on the counterfactual impact of attending.
Scoring
For each survey response, we assigned two scores on a scale from 0 to 1:
- Full-time equivalent (FTE) score: a rough measure of how much of the person's working time is now spent on AI safety–related work. For instance, someone running a successful university AI safety group part-time might score 0.2, someone working full-time in a technical AI safety role would score closer to 1. We used the following guidelines:
- Part-time research programmes (SPAR/AISC/MARS): 0.35 (average of expected programme commitments of 8-20 hrs per week)
- Research lead at a part-time research programme: 0.5
- Full-time programmes or full-time AI safety roles: 1
- Field-building:
- Running a group: 0.1
- Running a more involved group/Pathfinder fellowship: 0.2
- Running a national group/very active group: 0.3
- Thesis change:
- Undergraduate: 0.4
- Masters: 0.6
- PhD: 1
- Part-time research programmes (SPAR/AISC/MARS): 0.35 (average of expected programme commitments of 8-20 hrs per week)
- Counterfactual score: a measure of how much of that involvement is attributable to ML4Good specifically. For the first survey round (without a numerical self-reported counterfactual question), this was estimated by the assessor based on the participant's written description. For the second round, we used the participant's self-reported score, adjusting it only where the assessor judged it to be clearly over- or understated.
We then multiplied these two scores to produce a counterfactual FTE figure for each respondent, asking: "how much full-time AI safety work is this person doing as a direct result of ML4Good?"
We also tagged each respondent with categories describing their activities since the bootcamp (e.g. "further programme", "voluntary field-building", "technical research"), and flagged individuals who are currently upskilling or preparing for future roles, to distinguish them from those with no engagement at all.
Extrapolation to non-respondents
We expected that survey respondents are likely to be more engaged in AI safety than non-respondents, so extrapolating raw survey results would overestimate our overall impact. To correct for this, we manually researched non-respondents from three bootcamps (via LinkedIn) and scored them using the same criteria. We then calculated the ratio of non-respondent scores to respondent scores at those three bootcamps, and averaged these ratios.
We applied these ratios to estimate contributions from non-respondents for each of the remaining bootcamps, using the formula:
Extrapolated FTE total for bootcamp A = Bootcamp A total FTE from survey + (Bootcamp A total FTE from survey ÷ number of respondents) x Ratio x Number of non-respondents
These were calculated per-bootcamp then summed to get the total extrapolated FTE.
For counterfactual FTE, we calculated the ratio of counterfactual FTE to FTE among respondents (0.53 across all bootcamps) and applied it to the extrapolated FTE total.
There are a few additional caveats with this process:
- Not all non-respondents keep their public profiles up to date, so the manual research on non-respondents is likely an underestimate, especially of non-full-time work.
- Non-responders may be likely to attribute less of their success to ML4Good. We didn't have a way to account for this.
- Percentage of participants that responded >= 7/10 on the question “Would you recommend ML4Good to your friends with similar interests?”
- A small number of our attendees are already working to some degree in AI safety, and applied to the bootcamp to gain more context. This is under 1% of our attendees.
- In practice the timing has varied - as we batch our surveys, some alumni were surveyed around 2 months after their bootcamp, and others after over 6 months. As career changes often take more than a few months, responses from people surveyed soon after a bootcamp may not reflect longer-term outcomes.
- This counterfactual is based on participant self-report (the probability they would be doing this work without ML4Good) and assessment of written answers. For more details, please refer to Appendix 2.
- Note that our founder, Charbel-Raphaël Segerie, founded both ML4Good and CeSIA
- One of these respondents is working for ML4Good full-time, and others mentioned teaching part-time at ML4Good
- Our applicant pool is improving, because of a combination of growing interest in AI Safety and dedicated outreach work and 2026 bootcamps reliably have enough qualified applicants. However, in the past we have cancelled bootcamps or accepted fewer applicants due to a lack of applicants meeting our (non-arbitrary) threshold.

 点赞
 收藏
 点踩
 分享