TasteVal: Measuring the Experimental Research Taste of AI Systems Against Human Experts

We introduce TasteVal, a benchmark that measures the experimental research taste of AI models on AI R&D tasks. We define research taste as the ability to pick interesting problems to solve, design experiments, and interpret experimental results. TasteVal measures the experimental component of research taste; given a fixed research problem, we measure how well a model iteratively designs experiments and draws conclusions from their outcomes. In the AI Futures Model, experimental compute becomes the main bottleneck once coding is automated, so the time to superintelligence depends primarily on how fast research taste improves.
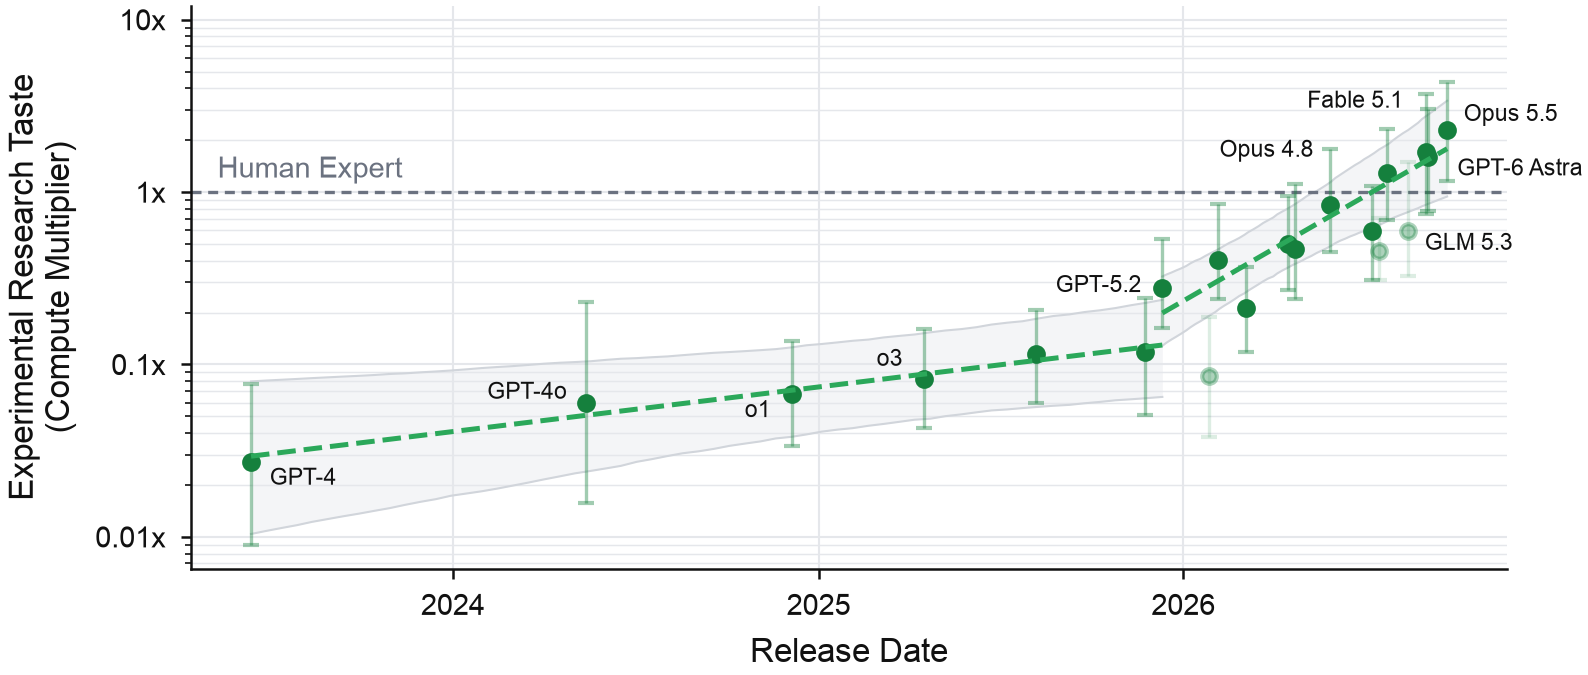
Setup. Given a fixed AI R&D problem, TasteVal measures how well a model designs experiments and draws conclusions from their results. We operationalize experimental research taste as compute efficiency: how much experimental compute a model needs to reach a given score, relative to human experts. A model that reaches the experts' score with half the experimental compute has twice their experimental research taste. Under this definition, doubling a model's experimental research taste has the same effect as doubling the compute available to run its experiments.
TasteVal consists of 8 novel tasks representative of frontier AI R&D, spanning pretraining data curation, pretraining and fine-tuning language models, preference modeling, and robustness to adversarial prompts. To isolate taste from coding ability, the model under evaluation only designs experiments and interprets their results, while a fixed coding agent implements and runs them on a single H100. A run ends when the model under evaluation has used 40 GPU-hours of compute or 120 hours of wall-clock time. Our human baseline is the best expert attempt on each task, drawn from 24 experts (at least two per task) who have recently worked at organizations including OpenAI, Google DeepMind, NVIDIA and Microsoft Research.
Results. The experimental research taste of frontier models has doubled every 3.0 months since December 2025 (95% CI 1.7-5.0 months). The best model, Opus 5.5, significantly exceeds our human baseline with a compute multiplier of 2.30x (95% CI 1.15-4.37x), at roughly 1/30 of our expert baseliners' average cost per attempt.
As a naive extrapolation rather than a forecast: if taste keeps improving at our measured rate per unit of general capability, the probability of a taste-only singularity rises from 51% to 88% in the AI Futures Project's AI Futures Model. Under the same assumption, the model's median arrival date for artificial superintelligence moves from mid-2030 to late 2028, and its probability of superintelligence before 2030 rises from 46% to 69%.
Limitations. Our results may overstate how fast the research taste is improving. Our tasks are fast and cheap to verify, which frontier labs find easiest to hill-climb, and our human baseline doesn't include top researchers, so it may significantly underestimate the best researchers in the world. TasteVal also doesn't measure a model’s ability to choose which problems are most fruitful to work on.
Our results may also understate how fast the research taste is improving. We did only limited elicitation of each model, spending about 1/30 as much per attempt on our best model as on our human experts.

 点赞
 收藏
 点踩
 分享