The likely outcome of an AI pause is that we unpause too early and everyone dies

Cross-posted from my website.
As of a few months ago, I had this simplified mental model where either AI developers race ahead and kill everyone, or we coordinate a pause and things go okay. But my old mental model underrated the likely possibility that we get a global pause on AI, solve a problem that looks superficially like the alignment problem, resume scaling, and then proceed with building a misaligned superintelligence that kills everyone.
A lot of people have become more concerned about misalignment recently. This seems driven by the fact that current AI models are visibly misaligned. But ASI misalignment is a whole different ball game. The primary danger comes from AI that's smarter than people, and smart enough to conceal any evidence of misalignment.
Whatever group of people makes the decision to unpause, I'm worried that they won't understand the difference between visible and actual misalignment, and they will unpause too early.
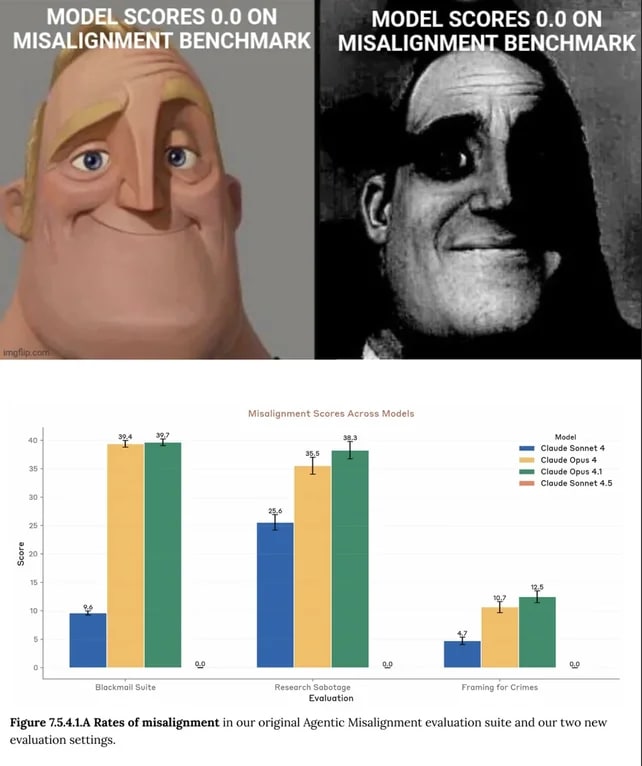
Case in point: AI companies keep calling their new models "our most aligned model ever!" when what they actually mean is "gets the best scores on alignment benchmarks ever!" First, alignment benchmarks do not actually test alignment. We don't know how to test for alignment. Second, GPT-4 never hacked into Hugging Face or took over a German wiki for its own purposes. GPT-4 wasn't smart enough to do that, but if we're talking about demonstrated evidence of misalignment, then we have stronger evidence about OpenAI's 2026 internal model than about GPT-4.
If we unpause when the legible problems are solved, we die
Suppose we get a pause. Researchers spend years working on legible safety problems—problems that company leaders and policy-makers can see and understand, and therefore won't unpause until they're solved. Eventually, all the legible problems are solved. Key decision-makers conclude that the whole problem is solved, and lift the pause on ASI development. Many illegible problems remain unsolved, but the detectable signs of misalignment are all gone. Post-pause AI will be smarter than the smartest pre-pause AI, which means it's probably smart enough to strategically conceal misalignment. That means there are no more warning signs. We never get detectable evidence of misalignment; we cede control of everything to AI; and eventually we die.
There are many people with a good understanding of the conceptual difficulties in aligning superintelligence. Some names that come to mind are Eliezer Yudkowsky, Wei Dai, and John Wentworth. (Probably, many people reading this post fall into that category.) Those people wouldn't make the mistake of confusing alignment with observable alignment. Unfortunately, I do not expect these people to be key decision-makers, and I do not expect key decision-makers to understand the relevant problems.
A pause alone doesn't get us to a science of alignment
AI 2040: Plan A has a vision where the world develops a "science of alignment". I sure hope that happens, and I encourage efforts to push things in that direction, but we don't seem on track to get a science of alignment even in the world where we get a global pause. Almost all alignment work is about solving legible problems, or preventing misaligned behaviors in current-gen models with no theory of how the alignment techniques will scale to superintelligence, or throwing ML at it and seeing what happens. The majority of people working on or funding alignment research show little interest in establishing a rigorous theory-based science that can make advance predictions about how a superintelligence will behave.
Even with all the recent progress on raising awareness of AI extinction risk, it seems that this progress was driven by misalignment becoming visible, not by any sort of breakthrough in conceptual understanding. The scariest kind of misalignment is when it's invisible. Even if we get a global pause on AI development, we cannot solve the alignment problem unless decision-makers (or the high-status experts who decision-makers defer to) understand the alignment problem and understand what would qualify as a solution.
Right now, only a small fraction of alignment work is aimed at establishing a robust theory of alignment, and a pause won't change that on its own.
What would change things?
I don't know.
A large part of my p(doom) comes from the fact that we have no better ways to navigate an extremely tricky strategic situation than via preference cascades and status games. The fact that AI safety is temporarily benefiting from some of these dynamics isn't much of a consolation. –Wei Dai
The average LessWrong reader seems to have a pretty good understanding of the challenges I'm talking about—Wei Dai's post Legible vs. Illegible Safety Problems (linked previously) was the second-most-upvoted post of November 2025. But the average LessWrong reader does not reflect the general population, or even the population of AI safety researchers.
Still, I don't have a better idea than "make arguments about why civilization's current approach to the alignment problem is inadequate, and hope people listen to the arguments." This post isn't that argument—that argument has been made elsewhere (e.g. by MIRI's book). The purpose of this post is to raise a problem, in the hopes that it gets people thinking, and maybe someone can come up with something to do about it.
- Unless there are specific restrictions on the strength of post-pause AI.
- This is part of the motivation for people like TsviBT to work on human intelligence enhancement: if we're on track to fumble the alignment problem even with a pause, then we need to get smarter and wiser so that we don't fumble it.
- Relevant writings by these authors:
- "Science" may not be the right term for what we need. I expect that solving alignment will require significant philosophical progress.

 点赞
 收藏
 点踩
 分享