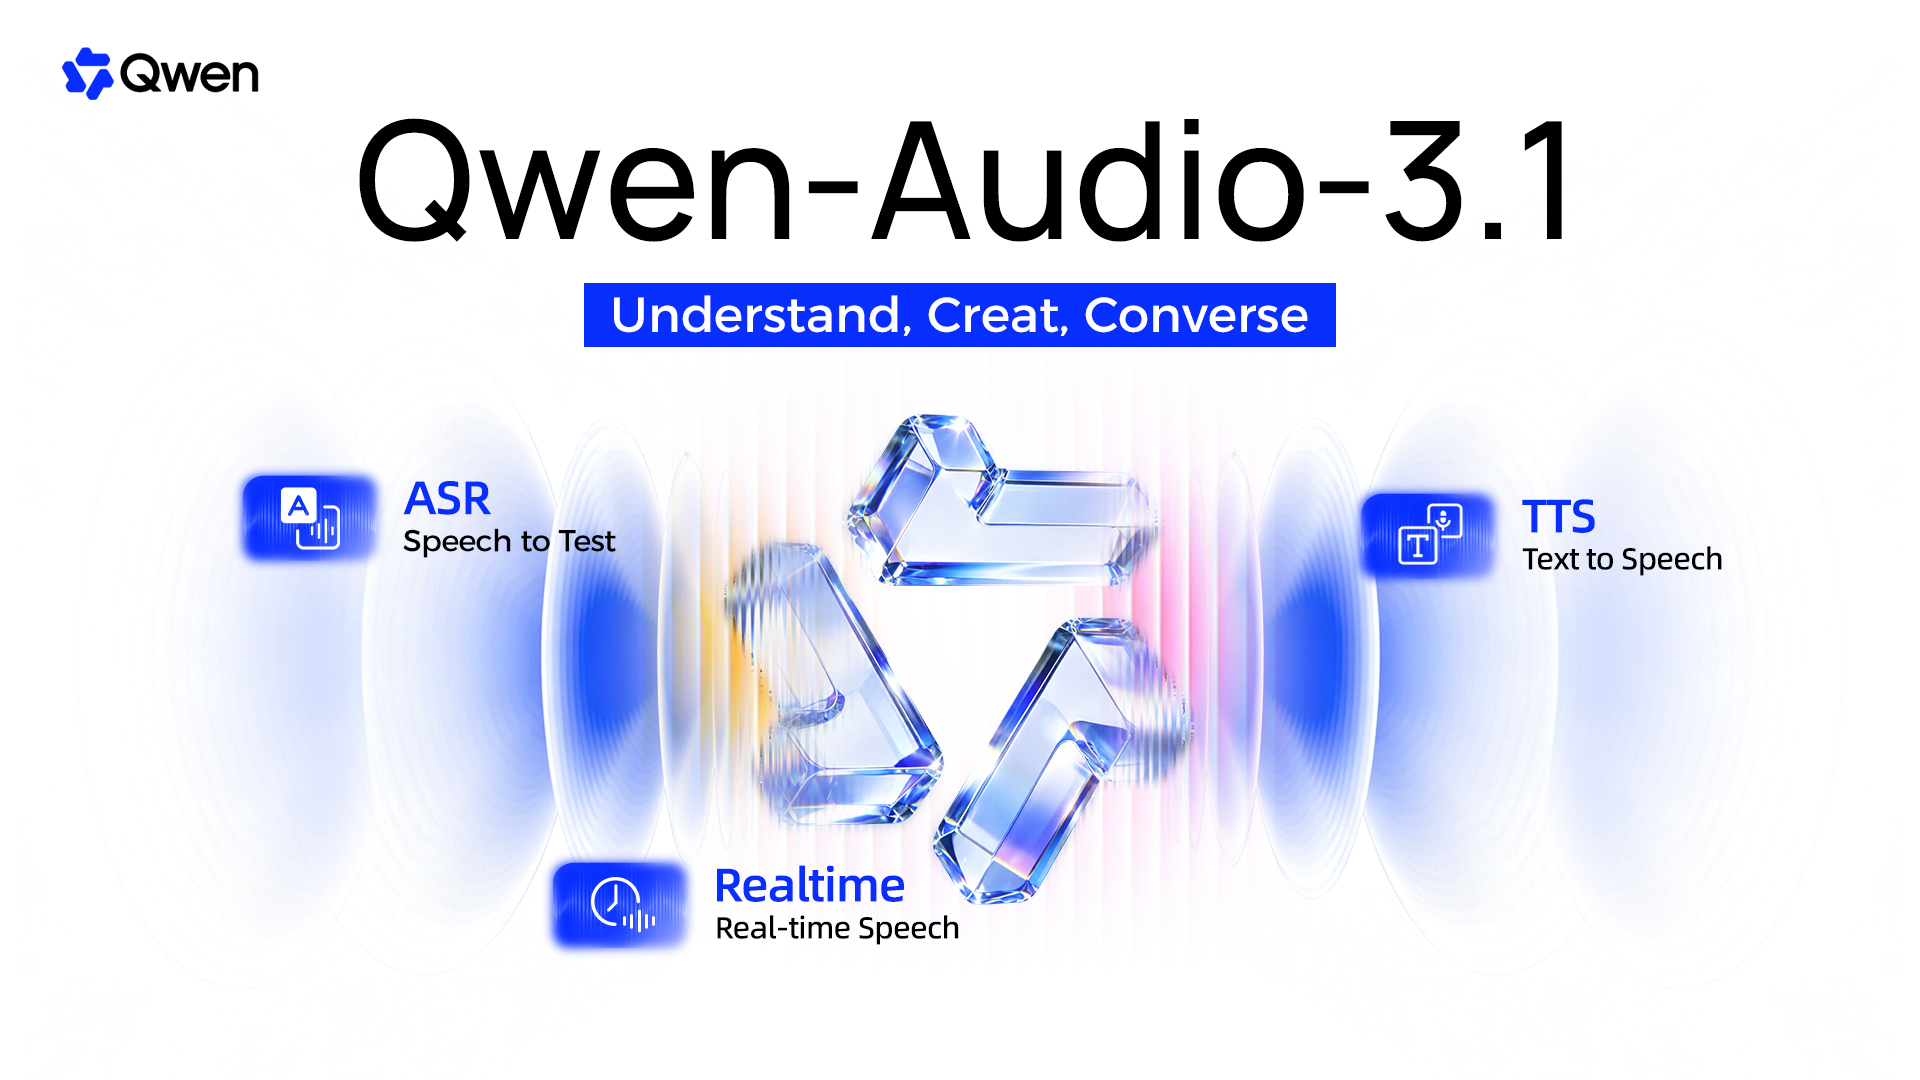
⚡ Meet Qwen-Audio-3.1! ASR, TTS & Realtime are fully upgraded, joined by two new models: TTS-Next for audio creation and ASR-Next for audio understanding.
Five models, one complete audio stack: understanding, generation, interaction & creation.
Plus big price cuts across the lineup: TTS ~70% off, Realtime ~85% off, and ASR up to 95% off.
Highlights: 🥳
- ASR: stronger multilingual & dialect recognition, plus native polishing that auto-removes fillers & repetitions for cleaner, more logical transcripts.
- ASR-Next: supports multi-speaker ASR with speaker labels, timestamps & aligned transcripts, and understands emotions, ambient & machine sounds for sound captioning, event localization, audio QA & reasoning.
- TTS: multilingual & dialect synthesis with natural cross-lingual voice transfer; control emotion, speed & style via simple instructions.
- TTS-Next: unified LM + diffusion framework generating voice, sound effects & background audio in one pass for audiobooks, podcasts, games & ads.
- Realtime: speak & listen at once with anytime interruption, just like a real call; it even slows down and responds empathetically when it senses a low mood.
Unlock the full potential of Qwen-Audio-3.1! 👇
- Blog: fun-resource-shanghai.oss-cn-shanghai.a...o_3_tts_blog_review_260918/index.shtml
- Qwen-Audio-3.1-ASR:
qwencloud.com/models/qwen-audio-3.1-asr-flash-filetrans
• Qwen-Audio-3.1-Realtime:
qwencloud.com/models/qwen-audio-3.1-realtime-plus
• More APIs: coming soon @qwen_cloud

 点赞
 收藏
 点踩
 分享
评论
?
参与讨论