What Is Jev? A Practical Guide to Typesafe AI’s Decision Model

TLDR: TypeSafe’s Jev makes fast, structured AI decisions with probabilities. Here’s how to use its Python SDK, how it compares with generative models based on real-world tests, and a proposed Casewright integration.
On 15 September 2026, TypeSafe AI introduced Jev, its first System One Model. Founder Diogo Almeida, a former OpenAI researcher who co-invented ChatGPT, announced the release on X after two years of development, describing a new kind of frontier AI model designed to make structured decisions that software can use directly.
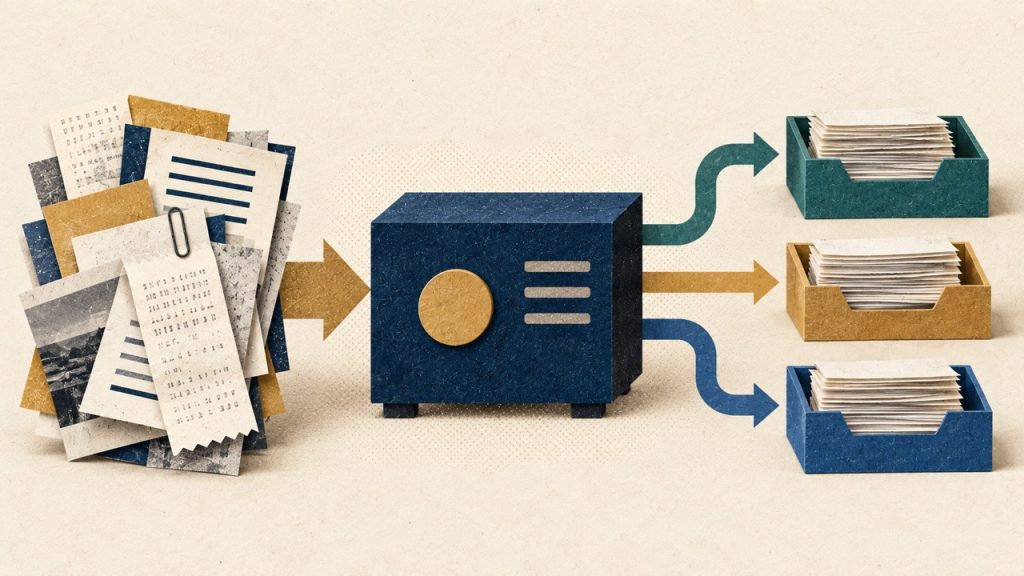
Jev accepts information, evaluates questions, and returns predefined answers with probabilities. It doesn’t generate free-form text. Developers can use those answers to classify documents, assess risk, route requests, or check an AI agent’s work.
Think of it as an AI-powered if statement. Your application supplies the information and questions, Jev returns its judgments, and your code decides what happens next.
How does Jev work?
Imagine you’re building customer support software. Someone sends this message:
I’ve been trying to connect my payment account for three days. It keeps failing, and I’m losing sales. Please help!
Your app needs to decide which department should receive the message, how urgent it is, and how frustrated the customer seems.
You could ask a generative AI model like Claude Opus or Google Gemini to evaluate the message and produce structured output. Jev handles the same task through three question types, which TypeSafe calls primitives.
With Choice, Jev returns the selected option and probability assigned to each alternative. Score returns a numerical position along your defined levels. Noul returns a number between zero and one, where 0.9 represents a 90% probability of yes.
You can combine all three in one API request. Each question evaluates the same information independently, with Jev processing the questions in parallel (up to 255 at once).
Questions don’t automatically receive the answers to other questions in the request. If a second judgment depends on the first answer, your app must submit another request containing that result.
How to use Jev in Python
TypeSafe provides a Python SDK for integrating Jev into existing software.
Install it with:
pip install typesafe-sdk
You’ll need an API key stored in the TYPESAFE_API_KEY environment variable.
Here’s an example using our customer complaint:
from typesafe_sdk import (Choice, Noul, Score, TypeSafeClient)

client = TypeSafeClient()
response = client.system_one(
    state="My payment account keeps failing. I'm losing sales!",
    questions={
    "department": Choice(
        instructions="Which team should handle this?",
        criteria={
            "billing": "Payment and subscription issues",
            "technical": "Bugs and integration failures",
            "sales": "Pricing and account questions",
        },
    ),
    "urgency": Noul(
        instructions="Does this message express urgency?"
    ),
    "frustration": Score(
        instructions="How frustrated is this customer?",
        criteria=[
            "Calm",
            "Frustrated",
            "Very angry",
        ],
    ),
   },
)

print(response.answers["department"].choice)
print(response.answers["urgency"].noul)
print(response.answers["frustration"].score)
The model returns typed answers that your application can access directly. TypeSafe’s documented example produces a department classification of technical, frustration score of 1.035, and urgency probability of 0.999 for a similar message.
Your software can then act on the answers:
urgency = response.answers["urgency"].noul
if urgency >= 0.9:
    priority = "high" else:
    priority = "normal"
This is an illustrative threshold; you’d still need to test Jev against labelled customer messages before using it in production.
Jev handles the semantic judgment, while normal code determines the workflow. You can change the questions, thresholds, and routing rules without having to train models yourself.
How does Jev differ from other artificial intelligence models?
OpenAI, Anthropic, and other providers already offer generative AI models that can produce structured output. OpenAI’s Structured Outputs feature, for example, uses constrained decoding to enforce supported JSON schemas.
So Jev’s ability to return valid structured data isn’t entirely new.
The architectural difference concerns how the model generates its answers. Conventional frontier models produce output tokens sequentially. TypeSafe says Jev uses a parallel sampler that evaluates multiple structured questions without generating text one token at a time.
TypeSafe also developed Reinforcement Learning for Calibrated Decisions (RLCD), a training method intended to align predicted probabilities with observed accuracy.
For example, if a model assigns 80% confidence to 100 comparable predictions, approximately 80 should be correct when the model is well-calibrated. Calibration doesn’t guarantee that any individual prediction is correct.
Jev provides probability distributions for Choice and Score questions, together with confidence values derived from those distributions. Noul returns its yes probability without a separate confidence field.
There’s still a role for other AI models. Claude, Gemini, OpenAI, and other open source models can generate explanations, reports, and code. Jev handles narrow judgments that software can combine into larger workflows.
Typesafe AI’s Jev: speed and pricing
TypeSafe reports response times of 70–500 milliseconds and charges $0.042 per million input tokens, with output tokens apparently free forever (too cheap to meter).
Its published workflow evaluations report improvements of up to 193.6 times in speed and 444.6 times in cost. The company acknowledges these figures represent the higher end of expected gains. Its benchmarks also use frontier model predictions as reference answers instead of independently verified ground truth.
Mike Taylor, head of evaluations at Every, conducted a separate hands-on test. He submitted 37 documents and asked 21 questions about each, producing 777 judgments in under 0.7 seconds at an estimated cost of a quarter of a cent.
A second test compared Jev with Claude Fable 5.1 across 12 writing samples. Jev took a median of 0.35 seconds per passage against Fable’s 8.83 seconds, but detected six of seven intended defects while Fable found all seven.
These early results provide useful measurements of speed, cost, and accuracy. Production performance still requires testing against the intended workload.
Where can developers use Jev?
TypeSafe’s use-case documentation describes several applications across AI engineering and automation.
For retrieval augmented generation (RAG), Jev could score document relevance, improve context engineering, and select which passages enter an LLM’s context. The same approach could support semantic search and RAG pipelines that need to assess hundreds of candidate documents.
For agentic AI systems, Jev could check tool calls, detect prompt injection, assess generated responses, and identify risky actions before execution. AI agents could also use Jev to decide whether a task requires additional information or another model.
And there’s an application for AI development tools. An AI engineer using Claude Code, OpenAI Codex, or other coding agents could add semantic checks to their workflows (similar to what ShipLock offers). Jev could inspect generated code against project conventions, evaluate an agent’s output, or flag changes requiring review.
TypeSafe provides an agent skill for Claude Code and other coding tools. The company’s use-case documentation also covers model routing, AI tooling, feature extraction, and guardrails.
Jev doesn’t replace the surrounding software, existing AI tools, prompt engineering, or an application’s business rules. Its integration provides structured decisions that those systems can use.
Using Jev in Casewright
I’ve been developing Casewright, an AI-powered chargeback representment engine that processes disputes, assesses merchant evidence, and prepares recommendations for analysts. I recently added periodic review and deployed a demo to the cloud.
Representment allows merchants to challenge chargebacks by submitting supporting evidence. According to Mastercard’s guidance, evidence must address the dispute reason code and meet the applicable submission deadline.
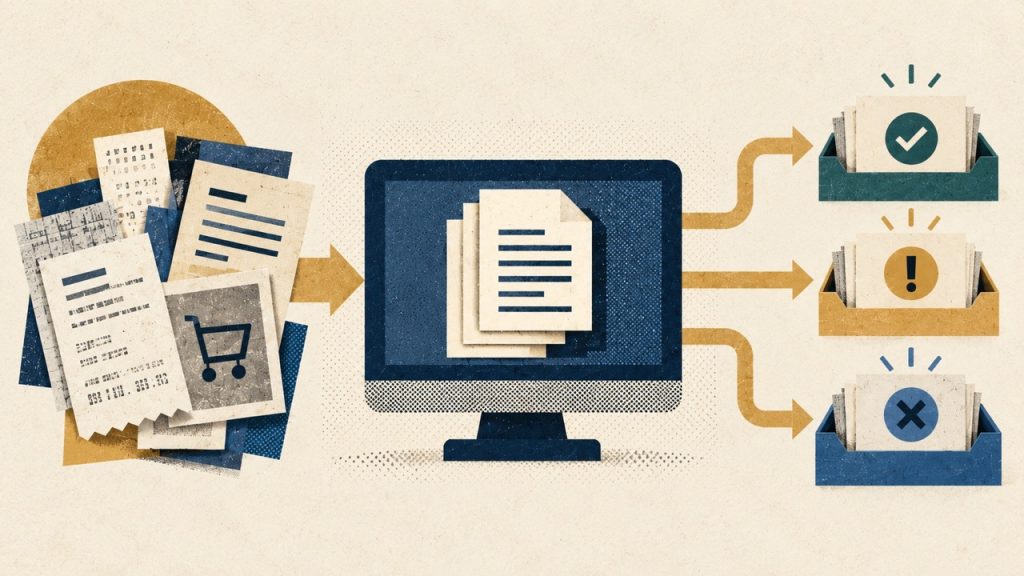
A case might contain transaction records, issuer narratives, merchant documents, and scheme requirements. The analyst needs to determine whether the evidence supports representment, whether information is missing, and whether accepting the chargeback makes more sense.
Casewright already uses LLMs to prepare case workups. Jev could provide additional checks during initial processing and periodic review.
For example, we could submit the reason code, scheme requirements, merchant evidence, and existing recommendation, then ask three questions:
questions = {
    "relevant": Noul(
        instructions=(
            "Does the merchant evidence directly address the dispute reason?"
        )
    ),
    "contradiction": Noul(
        instructions=(
            "Does the evidence contradict the issuer's narrative?"
        )
    ),
    "review": Noul(
        instructions=(
            "Does the case contain ambiguity requiring analyst review?"
        )
    ),
}
Each question would return a probability. Application code could combine those results with deterministic checks and decide whether to continue processing or request analyst review.
We’d retain ordinary code for deadlines, monetary calculations, mandatory documents, and other requirements that software can verify directly.
Periodic review provides another integration point. When new evidence arrives, Jev could evaluate whether it changes the basis of an earlier recommendation. Cases containing potential contradictions or material changes could return to an analyst.
How we’d benchmark Jev
Before introducing Jev into production, we’d need a golden dataset containing representative chargeback cases and verified answers.
Historical analyst decisions alone wouldn’t establish ground truth. Analysts can disagree, and a successful representment doesn’t prove every intermediate assessment was correct.
We’d need explicit labels for evidence relevance, contradictions, missing information, and review requirements.
The evaluation would compare Jev with Casewright’s existing model using identical cases and decision criteria.
We’d measure decision accuracy, false-negative rates, probability calibration, latency, and total cost per case. We’d also track analyst overrides and the proportion of cases requiring manual review.
Research on calibrated selective classification examines how models can use uncertainty to defer predictions while accounting for errors that occur despite high confidence.
We’d keep development cases separate from a held-out evaluation set, then assess performance across dispute reason codes, evidence types, and incomplete submissions.
Periodic review would let us measure whether Jev identifies changes requiring revised recommendations without repeatedly escalating cases whose evidence hasn’t changed.
Can Jev hallucinate?
TypeSafe says Jev can’t generate responses outside its predefined schema. Its own zero-hallucination figure refers to that structural guarantee, not an empirical measurement of factual accuracy.
Basically, if you define approve, reject, and review as permitted answers, Jev can’t invent a fourth category. But it can select approve when the evidence supports reject.
Valid answers aren’t always correct answers, even with high confidence scores.
Developers must still test calibration against their own data and account for the cost of incorrect decisions.
For Casewright, that means retaining evidence validation, scheme rules, and analyst oversight even when Jev reports high confidence.
Getting started with Jev
Jev currently operates through TypeSafe’s hosted API, with early access available through a waitlist. The quick-start guide covers API keys, Python installation, and the Playground.
Start with one repeated decision, define its permitted answers, and collect verified examples. Compare Jev’s accuracy, latency, and cost against your existing model before extending it to additional questions.
The post first appeared on Mohammed Shehu, PhD.

 点赞
 收藏
 点踩
 分享